Azure Data Engineer Training: Build Your Future in Cloud Data Engineering
Data is at the heart of almost every modern business. From customer transactions and application logs to sales reports and IoT devices, organizations generate enormous amounts of data every day.
But collecting data is only the beginning.
Businesses need professionals who can extract, transform, integrate, store, process, and prepare data for analytics and business intelligence.
This is where an Azure Data Engineer comes in.
Azure Data Engineering combines technologies such as SQL, Azure Data Factory, Azure Data Lake Storage, Azure Synapse Analytics, Python, PySpark, and Azure Databricks to build modern cloud-based data solutions.
If you are planning to start or advance your career in Data Engineering, Cloud Data Engineering, or Azure Data Engineering, a practical Azure Data Engineer Training program can help you build the skills required to work with real-world data platforms.
What Exactly Does an Azure Data Engineer Do?
An Azure Data Engineer is responsible for building and maintaining the systems that allow organizations to collect, process, transform, and store data.
Think of a data engineer as the person who builds the data highway connecting different business systems.
Data may come from:
- SQL Server databases
- Excel and CSV files
- Applications
- APIs
- Cloud storage
- Business applications
- IoT devices
- Enterprise systems
The data engineer connects these sources, moves the data into appropriate storage, transforms it, and prepares it for analytics.
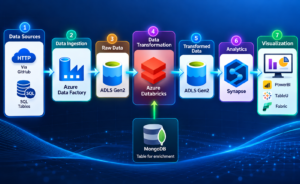
A typical workflow can be represented as:
Data Sources → Data Ingestion → Data Lake → Transformation → Data Warehouse → Analytics
Azure Data Factory is designed specifically for cloud-based data integration and orchestration, supporting ETL, ELT, data movement, transformation, scheduling, and monitoring.
Why Azure Data Engineering Has Become an Important Skill
Traditional data environments often require organizations to maintain multiple servers, databases, ETL tools, and infrastructure components.
Cloud platforms provide organizations with scalable services for storing and processing data.
Microsoft Azure provides an ecosystem of services that can be combined to create complete data engineering solutions.
For example:
SQL Server → Azure Data Factory → ADLS Gen2 → Azure Databricks → Azure Synapse → Power BI
Each service can perform a different part of the data journey.
This makes Azure Data Engineering more than simply learning one tool. It involves understanding how multiple technologies work together.
The Azure Data Engineering Technology Stack
A strong Azure Data Engineer Course should introduce learners to the major technologies used throughout the data lifecycle.
SQL Server and T-SQL
SQL is one of the fundamental skills for data engineering.
Before moving into advanced cloud technologies, it is important to understand how data is stored and queried in relational databases.
Important SQL concepts include:
- SELECT statements
- Joins
- Subqueries
- CTEs
- Window functions
- Views
- Stored procedures
- Functions
- Transactions
- Indexes
- Query optimization
- T-SQL programming
Strong SQL knowledge provides a useful foundation for working with cloud data platforms.
Azure Data Factory: Connecting the Data World
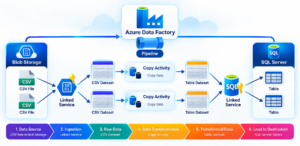
Azure Data Factory (ADF) is one of the key services used for data integration and pipeline orchestration.
It can connect to different data sources and help move and transform data through automated workflows.
With Azure Data Factory, data engineers can work with:
- Pipelines
- Linked Services
- Datasets
- Copy Activity
- Data Flows
- Parameters
- Variables
- Triggers
- Integration Runtime
- Pipeline monitoring
Microsoft documentation describes Data Factory as a managed cloud service for data integration and ETL/ELT workflows. It can connect different data stores, move data, transform it, and publish the results to analytical destinations.
Azure Data Lake: Building the Central Data Storage Layer
Modern organizations often need to store huge volumes of structured, semi-structured, and unstructured data.
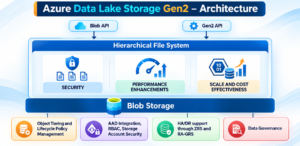
Azure Data Lake Storage Gen2 (ADLS Gen2) provides capabilities for big-data analytics within Azure Blob Storage and supports both file-system and object-storage approaches.
A data lake may organize information into different layers:
Raw Data → Cleansed Data → Transformed Data → Curated Data
An Azure Data Engineer should understand:
- Storage accounts
- Containers
- File systems
- Folder structures
- File formats
- Access control
- Permissions
- Data organization
- Data ingestion
Azure Synapse: Turning Data Into an Analytics Platform
After data has been collected and transformed, organizations need platforms where the data can be analyzed efficiently.
Azure Synapse Analytics provides capabilities for enterprise analytics and data warehousing and includes data integration capabilities based on Azure Data Factory.
An Azure Data Engineer may work with:
- Synapse workspaces
- SQL-based analytics
- Data warehousing
- Data integration
- Data pipelines
- Data lake integration
- Large-scale analytical workloads
Understanding how data moves from a data lake into an analytical environment is an important part of Azure Data Engineering.
Python and PySpark: Going Beyond SQL
SQL is essential, but modern data engineering often involves programming as well.
Python can be used for:
- Data transformation
- Automation
- File processing
- API integration
- Data validation
- ETL development
For large-scale data processing, PySpark provides a way to work with Apache Spark using Python.
This becomes particularly useful when dealing with large datasets and distributed processing workloads.
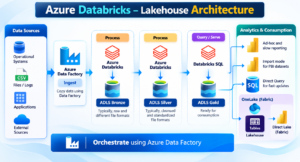
Azure Databricks: Processing Data at Scale
Azure Databricks is another important technology for modern Azure Data Engineers.
Microsoft describes Azure Databricks as a unified analytics platform supporting data engineering, analytics, AI, data warehousing, and lakehouse workloads. Its data-engineering capabilities combine Apache Spark with Delta and support languages including SQL, Python, and Scala.
Data engineers can use Databricks for:
- PySpark development
- ETL processing
- Data transformation
- Spark SQL
- Delta Lake
- Data pipelines
- Large-scale data processing
- Lakehouse solutions
How Does an Azure Data Pipeline Work?
Let’s consider a simple real-world scenario.
Suppose an e-commerce company receives customer and sales data from multiple systems.
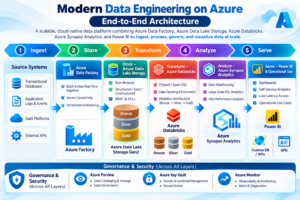
The workflow could look like this:
Step 1 – Data Sources
SQL Server, CSV files, APIs, and application databases generate data.
Step 2 – Data Ingestion
Azure Data Factory collects the data from different sources.
Step 3 – Data Lake
The incoming data is stored in Azure Data Lake Storage Gen2.
Step 4 – Data Transformation
Azure Data Factory, Python, PySpark, or Databricks can transform and cleanse the data.
Step 5 – Data Warehouse
Processed data can be loaded into an analytical platform such as Azure Synapse.
Step 6 – Reporting
Business users can consume the prepared data through analytics and reporting tools such as Power BI.
Azure Data Factory supports scenarios in which data is collected from different sources, transformed using Data Factory or external compute such as Azure Databricks, and published to analytical stores.
What Should You Expect From a Good Azure Data Engineer Course?
A good Azure Data Engineer Training program should go beyond presentations and theoretical concepts.
The learning experience should include practical exposure to:
- SQL and T-SQL
- Azure Data Factory
- Azure Data Lake
- Azure Synapse
- Python
- PySpark
- Azure Databricks
- ETL and ELT
- Data Warehousing
- Data Modeling
- Data Pipeline Development
- Pipeline Monitoring
- Troubleshooting
- Real-time projects
Microsoft’s own Azure Data Factory tutorials include practical scenarios such as copying data, incremental data movement, troubleshooting pipelines, working with ADLS Gen2, data flows, Databricks activities, and pipeline monitoring.
Build Your Skills Through Real-Time Projects
Projects are an important part of becoming comfortable with data engineering.
For example, an E-Commerce Data Engineering Project could include:
Customer Data
↓
Sales Data
↓
SQL Server / CSV / API
↓
Azure Data Factory
↓
Azure Data Lake Storage
↓
Databricks + PySpark
↓
Azure Synapse
↓
Power BI
Through such a project, learners can practice data ingestion, transformation, storage, orchestration, monitoring, and analytics as one connected workflow.
SQL School’s current Azure Data Engineer program also highlights a practical curriculum covering SQL Server/T-SQL, Azure Data Engineering, integrations and DevOps, an end-to-end industry project, certification preparation, and Microsoft Fabric for Data Engineering.
Who Can Learn Azure Data Engineering?
Azure Data Engineering can be suitable for professionals and learners coming from different technical backgrounds.
It can be useful for:
- Fresh graduates
- SQL Developers
- Database Developers
- SQL DBAs
- ETL Developers
- BI Developers
- Data Analysts
- Software Developers
- Database Administrators
- IT professionals moving toward cloud technologies
If you already know SQL or database concepts, you can build your Azure Data Engineering skills progressively.
Career Paths After Azure Data Engineer Training
After developing the required skills and practical experience, learners can explore roles such as:
- Azure Data Engineer
- Cloud Data Engineer
- Data Engineer
- ETL Developer
- Azure ETL Developer
- Databricks Data Engineer
- Big Data Engineer
- Data Warehouse Developer
- Cloud Data Developer
Job responsibilities and technology requirements can vary between organizations, so it is useful to review actual job descriptions while planning your learning path.
Why Choose SQL School for Azure Data Engineer Training?
SQL School Training Institute – Hyderabad focuses on practical, step-by-step technical training.
The Azure Data Engineer learning path covers technologies such as:
- MSSQL
- T-SQL
- SQL Query Tuning
- Azure Data Factory
- Azure Data Lake
- Azure Synapse
- Python
- PySpark
- Azure Databricks
- ETL
- Data Warehousing
- Real-Time Projects
- Scenario-Based Training
- Interview Preparation
- Resume Guidance
- 100% Placement Assistance
The focus is on helping learners understand how different technologies work together to create complete data engineering solutions.
Frequently Asked Questions About Azure Data Engineer Training
Is SQL necessary for Azure Data Engineering?
SQL is an important skill for working with relational databases, analytical platforms, and many data engineering workloads.
Can a SQL Developer become an Azure Data Engineer?
Yes. SQL experience provides a useful foundation. The next step is to learn Azure services, data pipelines, cloud storage, data processing, and related technologies.
Is Python required for Azure Data Engineering?
Python is highly useful for automation, data transformation, and data processing. PySpark is also valuable for large-scale data workloads.
What is Azure Data Factory used for?
Azure Data Factory is used for data integration and orchestration. It can connect to data sources, move data, transform data, schedule workflows, and monitor pipeline execution.
What is ADLS Gen2?
Azure Data Lake Storage Gen2 provides Azure storage capabilities designed for big-data analytics and supports both file-system and object-storage approaches.
Conclusion
Start your Azure Data Engineering journey by mastering SQL, Azure Data Factory, Data Lake, Synapse, Python, PySpark, and Databricks. With practical training and real-time projects, you can build the skills needed to work with modern cloud data solutions.
Learn. Practice. Build. Grow with Azure Data Engineering!
Azure Data Engineer Training: https://sqlschool.com/azure-data-engineer-training/
Start Your Azure Data Engineering Journey
Build practical skills in SQL, Azure, ETL, Data Factory, Data Lake, Synapse, Python, PySpark, and Databricks.
Learn step by step, practice real-world data pipelines, and gain hands-on experience through end-to-end projects.
Learn. Practice. Build. Grow.
Azure Data Engineer Training – SQL School, Hyderabad
Trainer: Mr. Sai Phanindra – Founder & Trainer
Call: +91 9666440801 / +91 9951440801
www.sqlschool.com

