#Microsoft Cloud Engineer

Microsoft Cloud Engineer is a stable and high-demand job role responsible for designing, deploying, and managing scalable cloud-based data and application platforms using Microsoft Azure. This promising career stream involves integrating data and services from multiple sources, building secure cloud architectures, and managing modern data environments.

Training Highlights

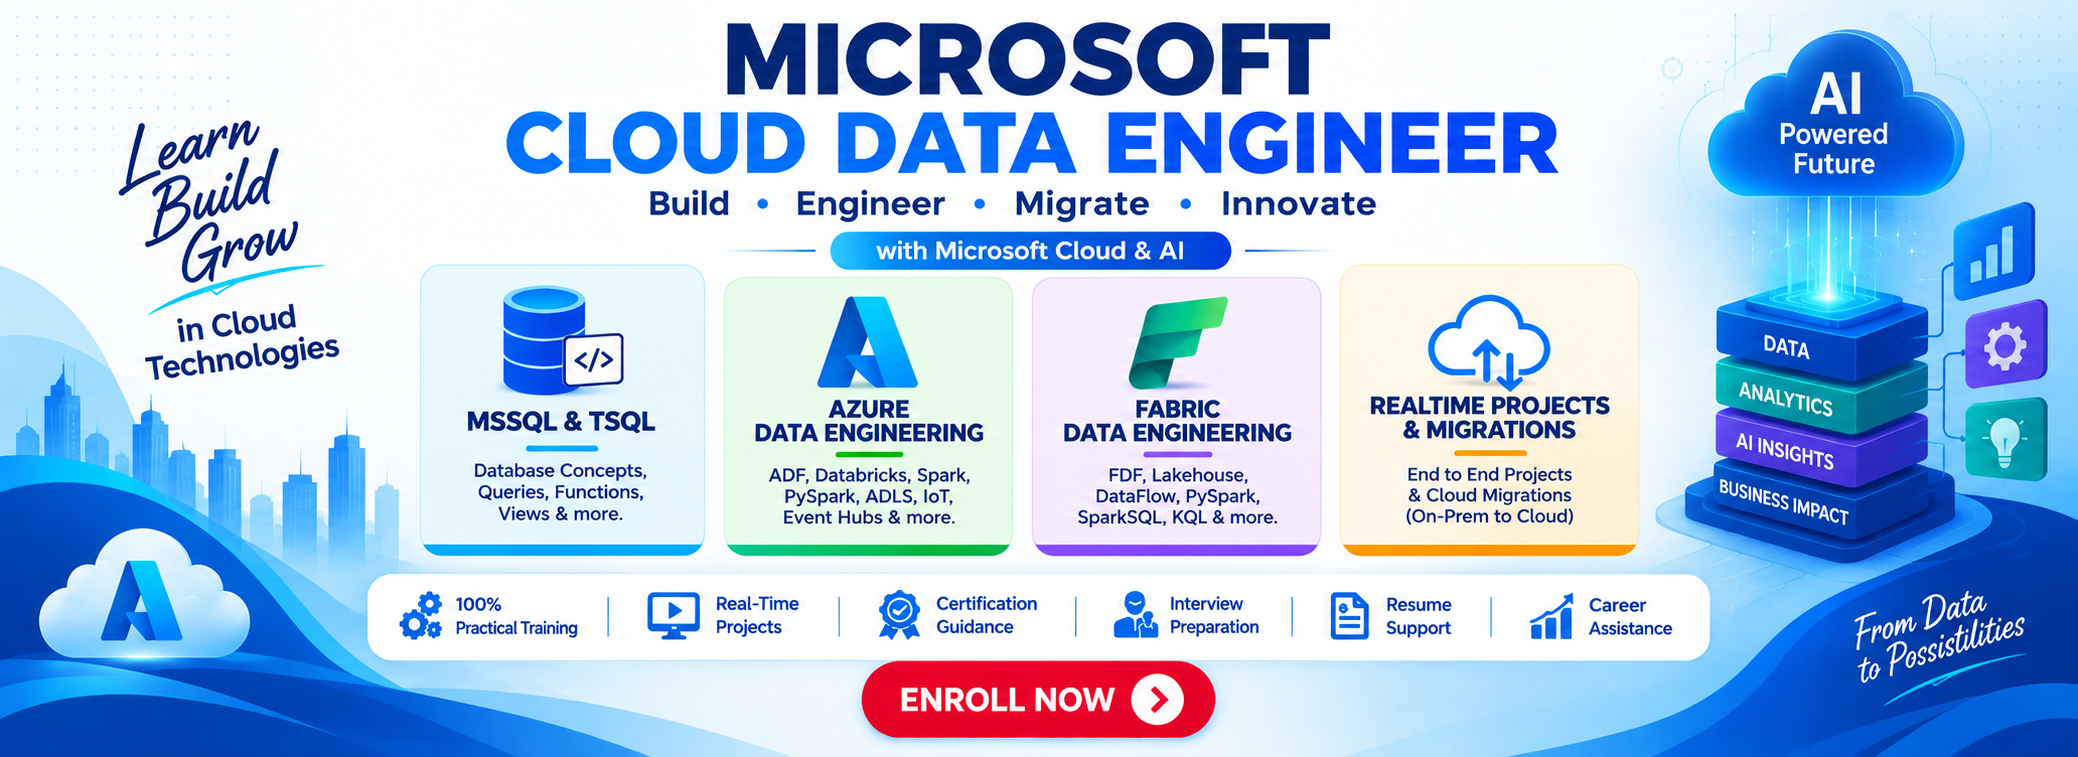
✅ MSSQL & Advanced T-SQL
✅ Azure Data Factory & Synapse Analytics
✅ Databricks – Spark, PySpark & Genie AI
✅ Microsoft Fabric Data Engineering
✅ Lakehouse, OneLake & Medallion Architecture
✅ Python, PySpark & Big Data Analytics
✅ End-to-End Real-Time Projects & Cloud Migrations
✅ DP-700, DP-750 & Databricks Certification Guidance

Modules We Learn:

✅ Module 1: MSSQL & TSQL
✅ Module 2: Azure Data Engineer
✅ Module 3: Fabric Data Engineering
✅ Module 4: Power BI
✅ Module 5: Realtime Project
Microsoft Cloud Data Engineer
Course Contents:

Module 1: MSSQL & TSQL

Ch 1: SQL Database Job Roles

  • Database Intro
  • OLTP, DWH, OLAP
  • DBMS Basics
  • Data Engineer Job Roles

Ch 2: Database Intro & Installations

  • SQL Server Installations
  •  Instance & Collations
  • SSMS Tool Installation
  • Connections, Authentications

Ch 3: SQL Basics V1 (Commands)

  • SQL Basics (DDL, DML, etc..)
  •  Creating Databases, Tables
  • Data Inserts (GUI, SQL)
  • Basic SELECT Queries

Ch 4: SQL Basics V2 (Commands, Operators)

  • DDL: Create, Alter, Drop
  • DML: Insert, Update, Delete
  •  DQL: Select, Fetch
  • Add, Truncate Statements
  • SQL Operators

Ch 5: Data Types & Variables

  • Integer Data Types
  • Character, MAX Data Types
  • Decimal & Boolean Data Types
  • Date and Time Data Types
  • SQL_Variant Type

Ch 6: Data Imports

  • Data Imports with Excel
  • Data Imports with CSV
  • Data Types Detection
  • OLE-DB Connections
  • ORDER BY, TOP, OFFSET

Ch 7: Schemas & Batches

  • Schemas & Table Grouping
  • Real-world Banking Database
  • 2 Part, 3 Part & 4 Part Naming
  • Batch Concept & “Go” Command

Ch 8: Constraints, Keys & RDBMS

  • Null, Not Null Constraints
  • Unique Key & Check
  • Primary Key Constraint
  • Foreign Keys, Default
  • DB Diagrams & ER Models

Ch 9: Normal Forms & RDBMS

  • Normal Forms: 1 NF, 2 NF
  • 3 NF, BCNF and 4 NF
  • 1:1, 1:M, M:1 Cardinality
  • Cascading Keys, Self Referencing Keys

Ch 10: Joins & Queries

  • Joins: Table Comparisons
  • Inner Joins & Matching Data
  • Outer Joins: LEFT, RIGHT
  • Full Outer Joins & Aliases
  • Self Joins & Aliases

Ch 11: Sub Queries

  • Basic Sub Queries
  • Aggregations
  • Combining Queries
  • Correlated Sub Queries
  • UNION, UNION ALL

Ch 12: Group By Queries

  • Group By, Distinct
  • GROUP BY, HAVING
  • Cube( ) and Rollup( )
  • Sub Totals & Grand Totals
  • Grouping( ) & Usage
  • ISNULL, COALESCE

Ch 13: Joins with Group By, Sub Queries

  • 3 Table, 4 Table Joins
  •  Join Queries & WHERE
  • Join & Group By, Sub Queries
  • IIF(), CASE Statement
  • EXISTS, NOT EXISTS
  • Query Execution Order

Ch 14: Views & RLS

  • Views: Realtime Usage
  • DML, SELECT with Views
  • WITH CHECK OPTION
  • Row Level Security (RLS)
  • Important System Views

Ch 15: Functions & Queries

  • User Defined Functions
  • Scalar, Table Value Functions
  • Variables & Parameters
  • Date & Time Functions
  • String Functions
  • Aggregated Functions
  • Data Conversion Functions

Ch 16: Advanced SQL & Window Functions

  • Window Functions (Rank)
  • Row_Number, DenseRank
  • Partition By & Order By
  • Lag & Lead Functions
  • Pivot, UnPivot
  • Running Totals
  • Moving Average

Ch 17: Stored Procedures – 1

  • Stored Procedures: Realtime Use
  • Parameters Concept with SPs
  • Procedures with SELECT
  • System Stored Procedures
  • Stored Procedures, Tuning

Ch 18: Stored Procedures – 2

  • Merge Statement (Upsert)
  • Merge with OLTP & DWH
  • Matched and Not Matched
  • Merge & SP Recompilations

Ch 19: Triggers & Automations

  • Need for Triggers in Real-world
  • DDL & DML Triggers
  • For / After Triggers
  • Instead Of Triggers
  • Disabling DMLs Triggers

Ch 20: Transactions & ACID

  • Auto Commit Transaction
  • Explicit Transactions
  • COMMIT, ROLLBACK
  • Checkpoint & Query Blocking
  • READPAST, LOCKHINT
  • TRY…CATCH & Error Handling

Ch 21: SQL Query Performance & Indexing

  • Clustered vs Nonclustered Indexes
  • Index Seek vs Scan
  • SARGable Queries
  • Tuning Queries
  • Indexing JOIN/WHERE columns
  • Query Optimization Examples

Ch 22: CTEs & Tuning

  • Common Table Expression
  • CTEs for Data Retrieval
  • CTEs for DML Operations
  • Data Cleansing Techniques
  • Duplicate Detection/Removal

Ch 23: Temp Tables & Query Techniques

  • Local & Global Temp Tables
  • SELECT..INTO Statement
  • Cursor Basics – When to Use & Avoid
  • NULLIF

Ch 24: Bonus / Advanced Module: SQL Server Internals

  • Database Engine Components
  • Parser, Compiler & Optimizer
  • Parsing and Compilation
  • Memory Manager & IO Managers

Real-Time Project 1 : HealthCare Domain
Project Requirement:
Solve 20+ Real-World Healthcare Business Requirements.

Project Workflow:
Database Design → SQL Development → Data Analysis → Performance Optimization

Project Operational Flow:
Healthcare DB → Patients → Doctors → Appointments → Treatments → Billing → Insurance → SQL
Analysis → Stored Procedures → Performance Tuning → Business Reports

Business Requirements:
Monthly Hospital Revenue, Top Doctors By Patients Treated, Repeat Patients, Department
Performance, Average Treatment Cost, Unpaid Bills, Insurance Claim Analysis, Patient Trends,
Month-Over-Month Revenue And Top Procedures…

Module 2: Azure Data Engineer

Section 1: Databricks (Spark, PySpark, Big Data, Genie AI)
Ch 1: Databricks Introduction

  • Cloud ETL, DWH
  • Cloud Computing
  • Databricks Concepts
  • ETL Components
  • Lakehouse & Big Data Concepts
  • Databricks Workspace UI
  • Databricks Account

Ch 2: Databricks Basic Operations

  • Catalog
  • Schema
  • Volumes, Files
  • Tables
  • Need for ETL
  • Need for PySpark
  • Catalog Explorer

Ch 3: Databricks Architecture

  • Databricks Architecture
  • Databricks Lakehouse Architecture
  • Databricks Runtime (DBR)
  • RDD & DAG
  • Spark Compute Concepts
  • Workers & Drivers
  • Databricks APIs

Ch 4: Unity Catalog

  • Unity Catalog Concepts
  • Catalogs & Volumes
  • Table Types
  • Parquet & Delta Tables
  • Managed & External Tables
  • Spark Table Creations

Ch 5: Spark SQL: Basics

  • Spark SQL Notebooks
  • Catalog, Schemas
  • Tables, Data Types
  • Notebooks: Exports, Clone

Ch 6: Spark SQL: Functions

  • Math, Sort Functions
  • String Functions
  • Date Time Functions
  • Conditional Statements
  • Window (Rank) Functions

Ch 7: Spark SQL: Time Travel

  • Time Travel Concepts
  • Spark DB: Logical Architecture
  • Describe, Extended
  • History, Versions
  • Timestamps, Data Recovery

Ch 8: Python: Introduction, Print

  • Python Introduction
  • Python Versions
  • Python in Databricks
  • Python Print()
  • Single, Multiline Statements

Ch 9: Python: Variables

  • Python Variables
  • Variable Declarations
  • Multi Variable Values
  • Common Variable Values
  • Variables in Real-Time

Ch 10: Python: Operators

  • Operators & Real-Time Use
  • Arithmetic Operators
  • Assignment Operators
  • Comparison Operators
  • Index Operators
  • Format Operators

Ch 11: Python: Data Types

  • Python Data Types
  • Integer / Int Data Types
  • Float, String Data Types
  • List Data Type
  • Dictionary Data Type
  • Tuple Data Type

Ch 12: Python: Control Statements

  • Python Control Structures
  • If … Else Statement
  • ELIF & ELSE IF Statements
  • FOR Loop & IF Conditions
  • Range & List Ranges
  • WHILE Loop

Ch 13: Python Modules & DataFrames

  • Python Modules
  • Pandas, NumPy
  • DataFrame Concepts
  • Handling Nulls
  • Data Cleansing Concepts
  • Python Functions

Ch 14: PySpark DataFrames & Transformations

  • Creating PySpark DataFrames
  • Reading Data Sources
  • select(), filter(), withColumn()
  • Handling NULL Values
  • Data Type Casting
  • Joins, Aggregations
  • Writing DataFrames

Ch 15: Medallion Architecture – 1

  • Medallion Architecture
  • Aggregated Data Loads
  • Bronze, Silver and Gold
  • Temp Views
  • Spark Tables (Parquet)
  • Work with File Sources

Ch 16: Medallion Architecture – 2

  • Medallion Architecture
  • Azure SQL DB Connections
  • Joining Source Tables
  • Data Frames, Temp Views
  • Aggregated Data Loads
  • Gold Data Consumption
  • Raw Sources → Bronze → Silver → Gold → BI/Analytics

Ch 17: Delta Lake

  • Databricks Delta Lake
  • Schema Evolution
  • Azure SQL DB Connections
  • DataFrames, Temp Views
  • Delta Table API
  • MERGE / Upsert Operations
  • Version History & Data Retention
  • Delta Transaction Log

Ch 18: PySpark: Widgets

  • PySpark Parameters
  • Text Widgets
  • User Parameters
  • Manual Executions
  • Automations
  • UI & JSON For Widgets

Ch 19: Lake Flow Jobs

  • Workflows & CRON
  • Job Compute, Running Tasks
  • Python Script Tasks
  • Parameters into Notebook Tasks
  • Parameters into Python Script Tasks
  • Concurrent Executions, Dependencies
  • Branching Control

Ch 20: PySpark: Auto Loader

  • Cloud Files Architecture
  • Checkpoint Configurations
  • Schema Location
  • Checkpoint Location
  • Data Stream
  • Schema Evaluation Modes
  • Incremental File Ingestion
  • Rescued Data Column

Ch 21: LakeFlow Declarative Pipelines

  • SDP: Spark Declarative Pipelines
  • Delta LIVE Tables
  • Streaming Data Loads
  • Bronze, Silver, Gold Data
  • Materialized Views
  • Pipeline Clusters
  • Data Quality Checks

Ch 22: Databricks Optimizations

  • Lazy Evaluation
  • Explain Plan
  • Caching, Data Shuffling
  • Broadcast Joins
  • Partitions, Data Skew
  • Liquid Clustering
  • VACUUM
  • OPTIMIZE, Z Ordering

Ch 23: Databricks Security, AI

  • ACL: Access Control List
  • Workspace Access Control
  • Catalog Security
  • Schema, Volume Security
  • Table Security
  • Column Security

Ch 24: Genie AI

  • Genie AI Concepts
  • Unity Catalog
  • AI Components in Databricks
  • Debugging Controls
  • Using AI for Notebook Design

Ch 25: GitHub & Asset Bundle

  • GitHub Concepts
  • GIT: Main, Branches
  • Asset Bundle
  • Integrating GIT with Asset Bundle
  • Process Integration

Ch 26: Apache Airflow

  • Apache Airflow Concepts
  • Airflow Operators & DAG
  • Python Scripts for Airflow
  • DatabricksRunNowOperator
  • DatabricksSubmitRunOperator
  • Airflow Jobs

Section 2: Azure Data Factory & Synapse, ADLS
Ch 1: Azure Fundamentals

  • Cloud Introduction, Azure
  • Cloud Implementations
  •  Azure Account, Subscription
  • Azure ETL & DWH Resources
  • Azure Storage, IoT Resources

Ch 2: Azure Storage & ADLS

  • Azure Data Lake Storage
  • Azure BLOB Containers
  • Access Keys
  • SAS Keys
  • IAM & ACLs

Ch 3: Azure Deployments, Azure SQL

  • Azure SQL Server Deployment
  • Azure SQL DB Deployment
  • Azure SQL Database (OLTP)
  • Azure Firewall Rules
  • Connections from SSMS Tool

Ch 4: Azure SQL DB Migrations

  • Azure Storage Account
  • On-Premise SQL DB, bacpac
  • Azure SQL DB Migration
  • SQL Server Imports from BLOB
  • Migration Verifications

Ch 5: Azure Synapse Analytics (DWH)

  • Synapse Pool Architecture
  • Control Node, Compute Node
  • DMS (Data Movement Service)
  • Azure DWH Tables: Partitions
  • Distributions & MAXDOP

Ch 6: Azure Data Factory – Pipelines

  • ADF Intro & Pipeline Artifacts
  • Integration Runtime (IR)
  • Linked Services, Datasets
  • Copy Data Activity
  • Azure SQL DB Loads
  • Azure Synapse Analytics Writes
  • Pipeline Validation, Runs

Ch 7: ADF: Azure Blob Data Loads

  • ADF Author & Pipeline Runs
  • Azure BLOB Storage Access
  • Storage Containers in ADF
  • Pipeline Staging
  • Pipeline Logging
  • Validations & Schedules

Ch 8: Table Incremental Loads

  • Implement SCD with ADF
  • Self Hosted IR: Realtime Use
  • On-premise Data: Incr Loads
  • Copy Method: Upsert, Keys
  • Staging & ADF Optimizations
  • Pipeline Logging

Ch 9: ADF Data Flow – 1

  • Creating Data Flow Items
  • Using Multiple Sinks
  • Conditional Split Transformation
  • Select, Sort, Union, Loops
  • ADF Debug Options

Ch 10: ADF Data Flow – 2

  • Working with Multiple Tables
  • Join Transform, Broadcast
  • Surrogate Keys, Derived Cols
  • ETL Loads Dates, Sink Options
  • Aggregated Data Loads

Ch 11: ADF Data Flow – 3

  • Pivot Transformation
  • Group By & Pivot Keys
  • Column Pattern, Deduplicate
  • Lookup, Cached Lookup
  • Tuing Transformations
  • Tuning Data Flow, Spark

Ch 12: ADF Data Flow – 4

  • Get Metadata
  • IF & Lookup Transformation
  • Cache Lookup
  • Broadcast Options
  • DIU, DOCP

Ch 13: ADF Parameters, Security

  • Linked Service Parameters
  • Creating Logins & Users
  • Schemas, ETL Permissions
  • Logins Parameters in ADF
  • Dynamic Linked Services

Ch 14: SCD & ETL with Control Tables

  • ADF Templates in Realtime
  • Incremental Loads (SCD)
  • Control Tables, Watermarks
  • Lookup Activity, Delta Queries
  • SP Activity & Parameters
  • Pipeline Parameters, SPs

Ch 15: ADF Metrics, Alerts

  • Azure Insights
  • Azure Metrics for ADF
  • Azure Metrics for Synapse
  • Alerts and Notifications
  • Action Groups, Tuning Options

Ch 16: ADF with DevOps & CI/CD

  • Git repositories and branching
  • ADF Git integration
  • Development / Test / Production environments
  • Parameterized deployments
  • Production release workflow

Ch 17: Azure Databricks

  • Azure Databricks Deployments
  • Azure Databricks Regions
  • Classic Deployments
  • Access connector for Databricks

Ch 18: Azure Databricks with ADLS

  • Creating IAM Users
  • ADLS Security for Databricks
  • Creating Service Principals
  • Enterprise Applications
  • Client ID, Secret ID
  • External Tables (Delta)

Ch 19: Azure Stream Analytics

  • Azure IoT Hubs
  • Azure Stream Analytics
  • LIVE Data Ingestions
  • SAQL Queries
  • Stream Analytics Jobs
  • Handling JSON Data

Ch 20: Azure Key Vaults

  • Azure Key Vaults
  • Azure Keys & Secrets
  • Access Policies
  • Secret Management
  • Managed Identity

Ch 21: Azure Logic Apps

  • Azure Logic Apps
  • Logic Apps & Automations
  • Azure Events
  • Azure Triggers & Signals
  • ADLS with Logic Apps

Real-Time Project 2: Online Travel Data Engineering Platform
Project Objective:

Build an end-to-end Azure Data Engineering solution to process, transform, and analyze Online Travel
business data from multiple sources.

Skills Gained:

  • Data Ingestion & ETL Development
  • Azure Data Factory Pipelines
  • Data Orchestration (End to End)
  • Data Lake Architecture, RBAC
  • Real-Time Industry Experience
  • Azure IoT, Stream Analytics
  • Azure Databricks with Data Factory

Components For Project

  • ADF Pipelines
  • Databricks Notebooks
  • Synapse Analytics
  • Apache Spark Schemas
  • Monitoring & Alerts
  • CI/CD Deployment
  • End to End Integrations
  • IAM & Managed Identity

Real-Time Project 3: Retail Sales Analytics Platform using Databricks (Medallion Architecture)
Project Overview

Students will build a production-style data platform using Lakehouse Architecture (Bronze, Silver, and
Gold), implementing modern ETL practices, data quality validation, incremental processing, orchestration,
optimization, and reporting.

Business Scenario
A multinational retail company receives daily data from multiple operational systems. The company wants
to build a centralized analytics platform to:

  • Consolidate data from different business domains
  • Improve data quality and consistency
  • Track sales performance across regions
  • Analyse customer purchasing behaviour
  • Monitor inventory levels
  • Generate business KPIs for decision-makers
  • Deliver Power BI dashboards with near real-time insights

Technologies Covered

  • Apache Spark
  • PySpark
  • Spark SQL
  • Delta Lake
  • Unity Catalog
  • Databricks Workflows
  • Git Integration
  • AirFlow

Project Workflow
Sources → ADLS → Databricks Workflows → Bronze → Silver → Gold → Analytics

Module 3: Fabric Data Engineering

Part 1: Fabric Concepts, DWH & Fabric Data Factory
Ch 1: Fabric Introduction

  • Need for Fabric, Big Data
  • Fabric Data Engineering Model
  • Fabric Components (Items)
  • Microsoft Fabric: Advantages
  • Azure Versus Fabric DWH

Ch 2: Fabric Account, Workspace

  • Need for Fabric Workspace
  • Workspace Creation Process
  • ETL, Storage, Analytical
  • Streaming, Monitoring
  • Compute & Separation

Ch 3: Fabric OneLake Architecture

  • Intelligent Data Foundation
  • Polaris Distributed Engine
  • Stateless & Stateful
  • Cache, Metadata, Xact & Data
  • Fabric Tasks, Inputs & DAG
  • State Machine & Statistics
  • Hot Spot Recovery

Ch 4: Fabric Warehouse

  • Fabric Warehouse Creation
  • Fabric Warehouse Properties
  • DWH Internal Operations
  • Default Schemas & Objects
  • SSMS Connections

Ch 5: Fabric Data Types

  • Exact, Approximate Numbers
  • Date and Time Data Types
  • Fixed & Variable Length
  • Binary & String Data Types
  • Fabric Type Limitations

Ch 6: Fabric Caching, Tuning

  • Fabric Caching Process
  • In-memory Cache, Disk Cache
  • Cache Types: LRU /MRU
  • Cold Cache / Cold Run
  • Warehouse Optimizations

Ch 7: Fabric Statistics, Tuning

  • Query Engine Options
  • Statistic Types
  • Auto, Manual Statistics
  • Update Statistics
  • Statistics Lists & Reports

Ch 8: Time Travel

  • Continuous Data Protection
  • Data Storage, Retention
  • FOR TIMESTAMP AS OF
  • Time Travel Scenarios
  • Time Travel on Queries

Ch 9: Zero Copy Cloning

  • User Layer, Storage Layer
  • Cloning & Parquet Files
  • Synapse Data Warehouse
  • Point In Time, Schema Level
  • Zero Copy Cloning Limitations

Ch 10: Fabric Security

  • Workspace Security
  • Warehouse Security
  • Item Security & Roles
  • Adding AD Users
  • MFA & Client Security

Ch 11: Fabric Copy Job

  • ETL Implementation Options
  • Copy Job Item
  • Data Loads with Copy Job
  • Full Loads
  • Testing Copy Jobs

Ch 12: Fabric Copy Job

  • Incremental Loads with Copy Job
  • Business Key Concept
  • DWH: Data Storage
  • Testing Initial Loads
  • Testing Incremental Loads
  • Copy Job Limitations

Ch 13: Fabric Data Factory

  • Need for Fabric Data Factory
  • ETL Operations in FDF
  • Data Sources, Transformations
  • Activities and Connections
  • Data Destinations (Sinks)
  • Creating Pipelines

Ch 14: Fabric Pipelines Design

  • Creation Options for Pipelines
  • Azure SQL DB Data Loads
  • Creating Data Sets
  • Copy Command Usage
  • Run ID & Monitoring
  • Pipeline Creation, Verification

Ch 15: Data Loads with Azure

  • Azure Data Lake Storage (ADLS)
  • Azure BLOB Containers
  • Fabric Data Loads From Azure Files
  • Fabric Warehouse with Azure
  • Run IDs and Activity
  • Compressions & Advantages

Ch 16: ETL Staging

  • Staging: Advantages
  • Caching & Storing Concept
  • Staging Types in Fabric
  • Workspace & External
  • External Stages in Pipelines
  • Pipeline Trigger, Monitor

Ch 17: Fabric Aggr Data Loads

  • Aggregation Scenarios
  • Creating Views in TSQL
  • Views in FDF Pipelines
  • Pipeline Editor
  • Data Loads to Warehouse
  • Pipeline Verifications

Ch 18: Fabric Incremental Loads – 1

  • Upsert (Incremental Loads)
  • Business Key Concept
  • SCD: Slowly Changing Dimension
  • Full Loads Vs Incr Loads
  • Testing Incrementing Loads
  • Pipeline Execution Tests

Ch 19: Fabric Incremental Loads – 2

  • Control Tables
  • Watermark Columns
  • Lookup Activity
  • Stored Procedure Activity
  • Parameters & Runs
  • Concurrency & Batch Count

Ch 20: OnPrem Gateways

  • On-Premise Gateway
  • Installing & Configuring
  • Authentication, Usage
  • On-Premise Connections
  • Pipelines for Data Loads
  • Warehouse Data Storage
  • Data Refresh with Gateways

Ch 21: Data Factory Pipeline Tuning

  • Intelligent Throughput
  • DOCP & Optimizations
  • Staging & In-Memory
  • Spark Compute Options
  • Concurrent Connections
  • ETL Partitions in Real World

Part 2: Fabric Data Flow, Lake House
Ch 1: Fabric Lakehouse

  • Fabric Lakehouse Architecture
  • Files and Tables Storage
  • Direct Lake & AI
  • Creating Lakehouse
  • Azure SQL Database Source
  • UI: Limitations

Ch 2: Lakehouse File Loads

  • Creating Lakehouse
  • Incremental Refresh
  • Computed Tables
  • Reusable Transformations
  • Scheduling, Monitoring

Ch 3: Power Query Level 1

  • Power Query Concept
  • Fabric Lake House
  • ETL, ELT Process with AI
  • Data Combine: Union, Append
  • Duplicate / Reference Queries
  • Warehouse Data Loads

Ch 4: Power Query Level 2

  • Table Transformations
  • Group By, Transpose
  • Header Row Promotion
  • Reverse Rows, Count Rows
  • Any Column Transformations
  • Data Type, Fill & Pivot

Ch 5: Power Query Level 3

  • Text Transformations
  • Format, SubString
  • Number Transformations
  • Date Time Transformations
  • Add Column Transformation

Ch 6: Power Query Level 4

  • Column From Examples
  • Conditional Column
  • Index Transformation
  • Duplicate Rows, Errors
  • Advanced Editor

Ch 7: Power Query Level 5

  • ETL Parameters
  • Big Data Access
  • Dynamic Parameters
  • List Queries
  • M Language Expressions

Ch 8: Stream House, KQL

  • Need for Stream House
  • Auto creation of KQL
  • Manual KQL Databases
  • Differences with Warehouse
  • Differences with Lakehouse

Ch 9: KQL Query Sets

  • KQL Database Extraction
  • File Imports – on Premises
  • Metadata Edit Options
  • Query Analytics
  • Exports, Visualizations

Ch 10: Fabric Data Activator

  • Need for Alerts, Notifications
  • Fabric Data Activator Options
  • Alert Conditions, Thresholds
  • Events & Email Notifications
  • Edit / Enable / Disable

Ch 11: Mirror Database

  • Need for Mirror Databases
  • Configure Mirror Databases
  • Data Replication
  • Connections & Usage
  • Mirror DB Practical uses

Part 3: Python, PySpark, DWH
Ch 1: Fabric Notebooks

  • Need for Notebooks
  • Fabric Notebook Types
  • Creating Environment
  • Creating Spark Clusters
  • Standard, High Concurrency
  • Magic Command

Ch 2: Spark SQL – 1

  • Spark SQL Notebooks
  • Creating Schemas
  • Delta Tables
  • Parquet Tables
  • Spark Joins
  • Data Partitioning
  • Union, Views in Spark

Ch 3: Spark SQL – 2

  • Math, Sort Functions
  • String, Date Time Functions
  • Conditional Statements
  • Data Recovery & Undo
  • Version Number
  • Describe Extended

Ch 4: Python Intro & Print

  • Python Introduction
  • Python Versions
  • Python in Spark (PySpark)
  • Python Print()
  • Single, Multiline Statements

Ch 5: Python Variables

  • Working with Variables
  • Printing Variables
  • Display Variables
  • Variable Types
  • Multi Value Variables
  • If … Else Statement

Ch 6: Python Operators

  •  Integer Operators
  • String Operators
  • Arithmetic Operators
  • Assignment Operators
  • Comparison Operators
  • Formatted Strings
  • Indexing Operators
  • ELIF, ELSE IF Statements

Ch 7: Python Data Types

  • Python Data Types
  • Integer / Int Data Types
  • Float, String Data Types
  • List Data Type
  • Dictionary Data Type

Ch 8: Python Dataframes

  • Pandas Module (Python)
  • Dataframes from Lists
  • Dataframe from Dict
  • Pandas Dataframes
  • Dataframe print, display

Ch 9: Python Dataframes Transformations

  • Append
  • Append with NoIndex
  • Merge with ON, KIND
  • spark.read.csv()
  • spark.read.format()

Ch 10: Medallion Architecture

  • Bronze, Gold and Silver
  • Raw Data
  • Data Preparation (Prepping)
  • Temporary Views
  • Big Data Analytics

Ch 11: PySpark: Medallion Loads 1

  • Data Prep (Silver)
  • Filtering DataFrame Records
  • Removing Duplicate Records
  • Sorting and Limiting Records
  • Spark SQL Dataframes
  • Gold Layer Implementation
  • Testing Aggregated Loads

Ch 12: PySpark: Medallion Loads 2

  • Azure SQL DB Connections
  • SQL Queries in PySpark
  • Data Prep (Silver)
  • Filtering Null Values
  • Grouping and Aggregating
  • Spark SQL Dataframes
  • Gold Layer Implementation
  • Notebook Utilities

Ch 13: PySpark: SCD

  • Slowly Changing Dimension
  • Merge Into Statement
  • Error Handling
  • Merge with OLTP Data Sources

Ch 14: PySpark: Widgets

  • Notebook Parameters
  • Text Widgets
  • Parameters & JSON
  • Notebook Schedules, Retry
  • Modular Notebook Design
  • Notebook Chaining

Ch 15: LakeHouse Architecture Optimizations

  • Delta Log
  • Delta Versioning
  • Partition Strategy
  • Small File Problem
  • Adaptive Query Execution
  • Explain Plan, Spark UI
  • mssparkutils

Ch 16: LakeHouse Optimizations

  •  VACUUM, OPTIMIZE
  • ZORDER
  • Broadcast Join
  • Cache, Persist
  • Shuffle Optimization

Ch 17: Semantic Models

  • Creating Semantic Model
  • Spark SQL: DDL, DML
  • Adding Refences, Keys
  • Using Model Layouts

Ch 18: Fabric Security

  • Workspace Security
  • Lakehouse Security
  • Security Principals
  • Authentication Options
  • MFA (Multi Factor Authentication)

Ch 19: Fabric Migrations

  • Azure Data Factory to Fabric Data Factory
  • Azure Synapse to Fabric Warehouse
  • Azure One Lake Migrations
  • Realtime Migration Considerations

Realtime Project 4: ECommerce Platform using Microsoft Fabric
Business Scenario

A multinational e-commerce company wants to centralize sales, customers, products, orders,
inventory, logistics and payment data into Microsoft Fabric.

Goal:
Create a scalable Fabric Data Platform capable of processing millions of records daily.

Skills Gained:

  • Fabric Pipelines
  • Fabric Notebooks
  • Fabric Data Flow
  • Semantic Models
  • Medallion Architecture (Bronze/Silver/Gold)
  • Real-Time Industry Experience
  • Fabric APIs (REST, Workspace)
  • Azure to Fabric Migrations
  • ADF Migrations
  • Synapse Migrations

Components For Project (From Resume Perspective):

  • Bronze
  • Silver
  • Gold
  • PySpark
  • CI/CD
  • End to End Integrations
  • DP-700 Exam: Complete Guidance

Module 4: Power BI

Ch 1: Power BI Intro, Installation

  • Power BI & Data Analysis
  • Power BI Eco System
  • Power BI Design Tools
  • Power BI Installation

Ch 2: Report Design Concepts

  • Basic Report Design (PBIX)
  • Data Points, Spotlight
  • Visual Interactions & Edits
  • Focus Mode, PDF Exports

Ch 3: Grouping, Hierarchies

  • Creating Groups: Lists
  • Creating Groups: Bins
  • Hierarchies & Drilldowns
  • Drill Up, Conditional DrillDown

Ch 4: Slicer & Visual Sync

  • Slicer Visual in Power BI
  • Slicer: Format Options
  • Single Select, Multi Select
  • Slicer: Select All On / Off
  • Visual Sync with Slicers

Ch 5: Filters & Drill Thru

  • Power BI Filters
  • Basic, Top & Advanced
  • Visual Filters, Page Filters
  • Report Level Filters, Clear Filter
  •  Drill Thru Filters & Usage

Ch 6: Bookmarks, Buttons

  • Power BI Bookmarks
  • Images: Actions, Bookmarks
  • Buttons: Actions, Bookmarks
  • Page to Page Navigations
  • Score Cards, Master Pages

Ch 7: SQL DB Access & Big Data

  • SQL DB Access, Queries
  • Storage Modes: Direct Query
  • Formatting & Date Time
  • Storage Modes in Power BI
  • Data Modeling & Formatting

Ch 8: Power BI Visualizations

  • Charts, Bars, Lines, Area
  • Tree Maps & Axis Items
  • Funnel, Card, Mult-Row Card
  • Pie Charts & Waterfall
  • Scatter Chart, Play Axis
  • Infographics, Classifications

Ch 9: Power Query Transformations – 1

  • Power Query (Mashup)
  • ETL Transformations in PBI
  • Table Combine Options
  • Merge, Union All Options
  • Missing Values, Duplicate Records
  • Wrong Data Types, Outliers
  • Close, Apply & Visualize

Ch 10: Power Query Transformations – 2

  • Group By Transformation
  • Aggregate, Pivot Operation
  • Reverse Rows, Count Rows
  • Data Cleaning, Null Handling
  • Data Type Detection, Change
  • Rename, Replace, Move
  • Fill Up, Fil Down

Ch 11: Power Query Transformations – 3

  • String / Text Transformations
  • Split, Merge, Extract, Format
  • Numeric and Date Time
  • Add Column & Expressions
  • Column From Examples

Ch 12: Power Query Transformations – 4

  • Parameters in Power Query
  • Static Parameters, Defaults
  • Dynamic Dropdowns, Lists
  • Linking with Table Queries
  • Step Edits, Type Conversions

Ch 13: Power BI Cloud & Fabric

  • Power BI Cloud, Microsoft Fabric
  • Microsoft Fabric Concepts
  • Fabric One Lake (DWH, LH, etc.)
  • Microsoft Fabric Workspace
  • Report Uploads (PBIX)
  • Report Edits, Semantic Models

Ch 14: Power BI Cloud Dashboards

  • Power BI Dashboards
  • Dashboard Creation, Usage
  • Pin Visuals, Pin LIVE Pages
  • Add Image, Video Tiles
  • Q&A & Pin Tiles

Ch 15: Power BI Cloud Operations

  • Report Shares, Alerts
  • Subscriptions, Exploration
  • Downloads & Edits
  • Report Cloning in Cloud
  • QR Codes, Web Publish
  • Lineage & Metrics

Ch 16: Power BI Cloud Gateways

  • Data Gateways, Data Refresh
  • Install, Configure Gateways
  • Data Refresh & Scheduling
  • Gateway Optimizations
  • Incremental Refresh

Ch 17: Power BI Cloud Apps

  • Power BI Apps: Creation
  • App Sections & Content
  • Audience & App Security
  • App Updates, Favorites
  • App URL, End User Access

Ch 18: Power BI Report Server, RDL

  • Power BI Report Server
  • RS Config Tool Options
  • Report Database, TempDB
  • Web Service & Server URL
  • Report Builder Tool
  • Paginated Report (RDL)

Ch 19: DAX Concepts & Calculations

  • DAX Concepts: Intro & Realtime Need
  • DAX Columns: Creation, Use
  • DAX Measures: Creation, Use
  • DAX Functions: IIF, ISBLANK
  • SUM, CALCULATE Functions

Ch 20: DAX Quick Measures

  • Quick Measures in Power BI
  • Running Totals
  • Star Rating Calculations
  • DAX Measures in Data View
  • DAX in Cloud Reports

Ch 21: Data Modelling

  • Dimensions Tables
  • Fact Tables & DAX Measures
  • Data Models & DDAX Joins
  • Star & Snowflake Schemas
  • Many-to-Many Relationships
  • Calculation Groups

Ch 22: DAX Joins, Variables

  • CALCULATEX & Variables
  • COUNT, COUNTA, etc..
  •  SUM, SUMX, etc..
  • SELECTED MEMBER
  • Filter Context, RETURN

Ch 23: DAX Models & Calculations

  • VAR, SWITCH, SUMMARIZE
  • TREATAS, USERELATIONSHIP
  • CROSSFILTER, GENERATE
  • RANKX, TOPN, WINDOW
  • OFFSET, INDEX

Ch 24: DAX Time Intelligence

  • Date Table Generation
  • Time Intelligence with DAX
  • PARALLELPERIOD, DATE
  • CALENDAR, Total Functions
  • YTD, QTD, MTD with DAX

Ch 25: DAX – Row Level Security

  • RLS: Row Level Security
  • Data Modelling & Roles
  • CoPilot & RLS, KPIs

Ch 26: DAX – Analytical Reports

  • Analytical Reports
  • Virtual Cube Concepts
  • Cross Filter Reporting
  • Alerts, Data Activator

Ch 27: PL 300 Exam Guidance

  • PL 300 Exam Guidance
  • Exam Samples
  • Exam Scenarios

Module 5: Realtime Project (End to End)

Realtime Project 5: Enterprise Healthcare Data & Analytics Platform
Project Objective

Design and implement a modern Healthcare Data Platform using Power BI Analytics and Reporting services
to process patient, hospital, clinical, and operational data for reporting, analytics, and decision-making.

Technologies Used

  • Azure Data Factory
  • Azure Data Lake
  • Azure Synapse
  • Databricks API
  • Power BI Service

Learning Outcomes
After completing this project, you can confidently showcase experience in: End-to-End Azure Data
Engineering Solutions

Project Flow
Source → Data Lake → Transformation → Warehouse/Lakehouse → Model → Power BI

Cloud Engineer Training FAQ's

What is Cloud Engineer Job Role?

A Cloud Engineer is responsible for designing, deploying, managing, and supporting cloud infrastructure and services across platforms like Azure, AWS, GCP, and hybrid clouds. The role involves working on cloud architecture, security, automation, monitoring, migration, and optimization. Cloud Engineers ensure that organizations’ applications and data operate securely, reliably, and cost-effectively in the cloud.

What are the Job Roles of a Cloud Engineer?

💼 Top Job Roles:


  • 1️⃣ Design and deploy scalable cloud infrastructure and solutions
  • 2️⃣ Manage and automate cloud resources using tools like Terraform, ARM, CloudFormation
  • 3️⃣ Configure security controls, identity management, and network settings
  • 4️⃣ Monitor, troubleshoot, and optimize cloud workloads
  • 5️⃣ Migrate on-premises systems to the cloud
  • 6️⃣ Ensure cloud compliance, backup, and disaster recovery and more..!

What does our Cloud Engineer Training course contains?

The course is carefully curated with below module:
👉🏻Module 1: Azure Data Engineer
👉🏻Module 2: Fabric Data Engineer
👉🏻Module 3: AWS Data Engineer
👉🏻Module 4: Snowflake Data Engineer

Who can join this course?

  • Freshers looking to start a career in cloud computing

  • System administrators transitioning to cloud infrastructure roles

  • Developers and DevOps engineers aiming to master cloud platforms

  • IT professionals seeking multi-cloud skills (Azure, AWS, GCP)

  • Anyone passionate about cloud technologies and modern IT solutions

No prior coding experience is required. All concepts are taught from scratch

What training modes are available?

Option 1:        LIVE Online Training  (100% Interactive, step by step, assignments)

Option 2:        Self Paced Videos (100% practical, step by step with concept wise assignments)

You may choose any one of these options, same curriculum!

I (Trainer) shall be available for doubts and clarifications, assignment check and review.

Why should I choose SQL School for Cloud Engineer training?

👉🏻 Every session is Practical, Step by Step with Concept wise FAQs !!

👉🏻 100% results with on-time practice.  Daily Tasks for every session.

👉🏻 Concept wise tasks be submitted before next class for Job Waiters / Starters.

👉🏻 Concept wise tasks due for submission by Weekends for Working Professionals.

Demo Videos

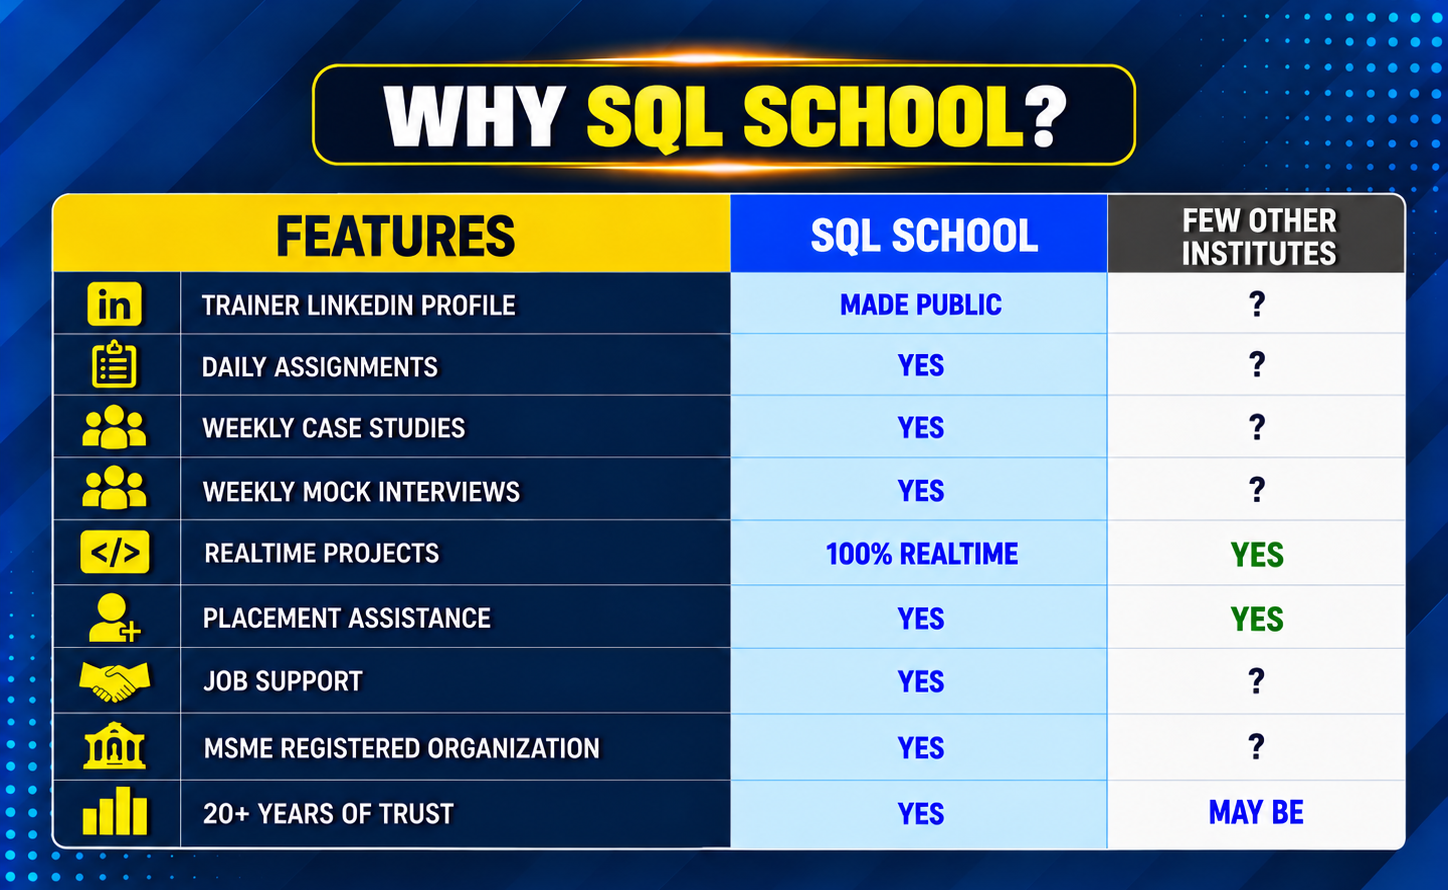
Why SQL SCHOOL?

Training Modes

Why Choose SQL School

  • 100% Real-Time and Practical
  • ISO 9001:2008 Certified
  • Concept wise FAQs
  • TWO Real-time Case Studies, One Project
  • Weekly Mock Interviews
  • 24/7 LIVE Server Access
A man smiling and giving a thumbs up while holding a notebook.
  • Realtime Project FAQs
  • Course Completion Certificate
  • Placement Assistance
  • Job Support
  • Realtime Project Solution
  • MS Certification Guidance

SQL School Azure Data Engineer training certificate of completion issued in January 2026 with verification ID
Verified by MonsterInsights