


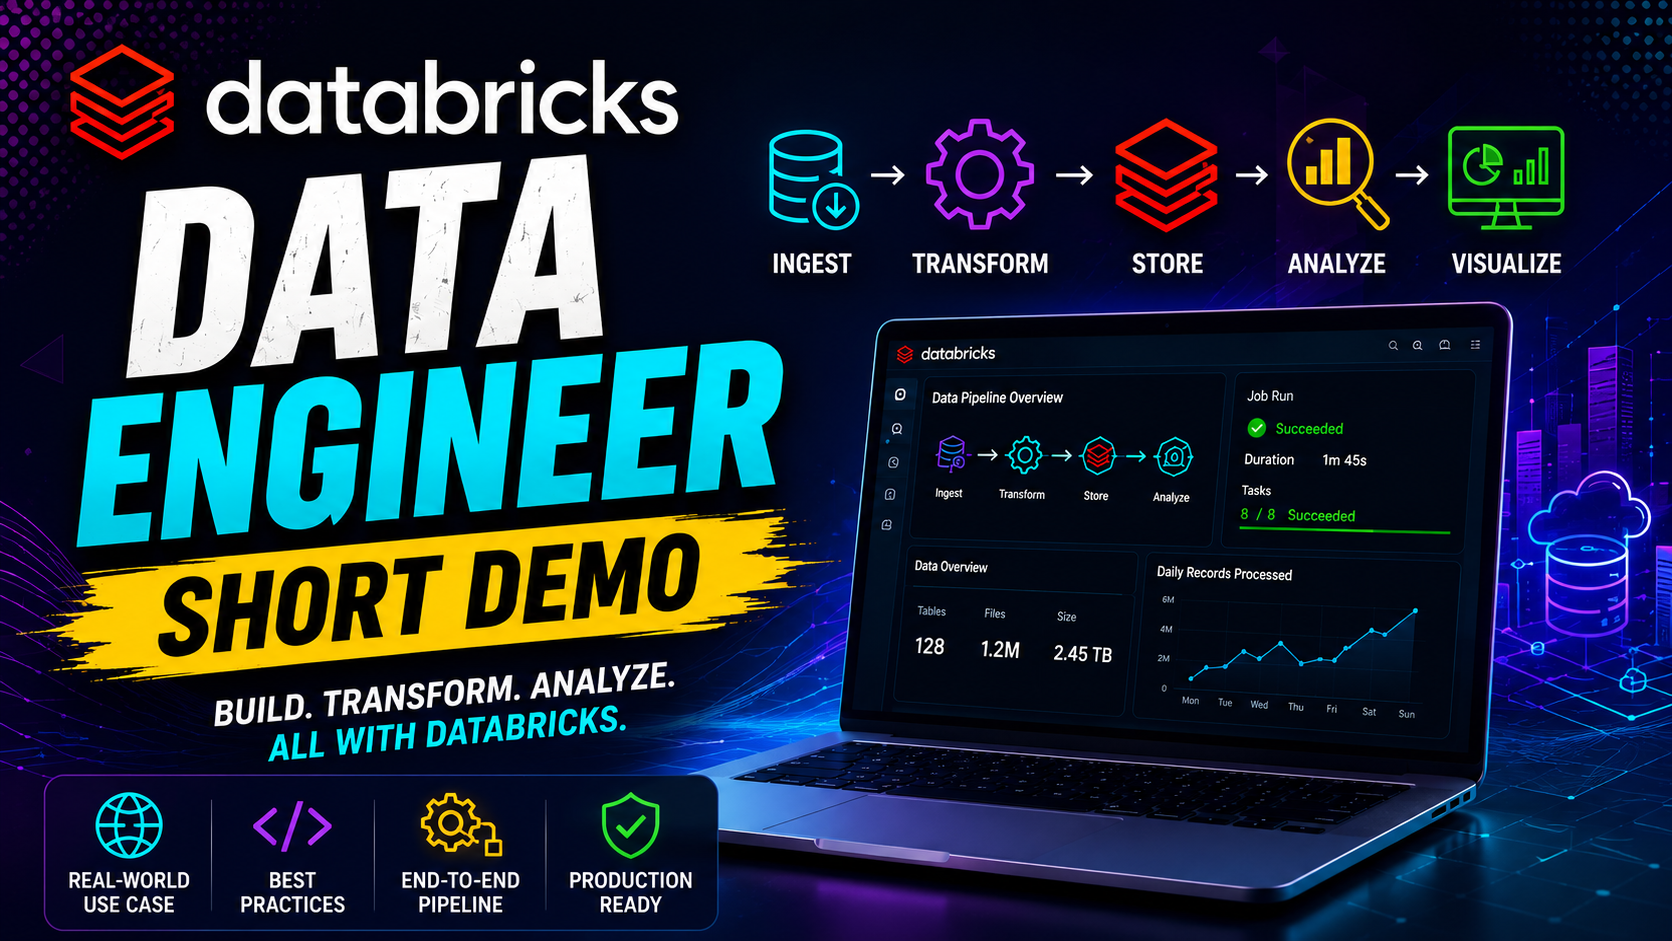
Databricks Data Engineer is the backbone of today’s data-driven world — uniting data, analytics, and AI on one collaborative platform. Built on Apache Spark, it enables seamless data integration, scalable ETL pipelines, and real-time analytics.
From finance to healthcare, Databricks Data Engineers power intelligent insights, optimize data workflows, and drive business transformation across industries.
Training Highlights
✅ Databricks Architecture
✅ PySpark & Spark SQL
✅ Delta Lake & Delta Tables
✅ Databricks Notebooks
✅ Python, PySpark, SQL
✅ Event Hub, Kafka
✅ Job Workflows & Automation
✅ CI-CD Integrations (DevOps)
✅ Real Time Projects
Modules We Learn:
✅ Module 1: SQL Server (MSSQL) & T-SQL
✅ Module 2: Databricks Data Engineering – Python, Spark & PySpark
✅ Module 3: Real-Time Project
✅ Module 4: Databricks Data Engineer Associate Certification Guidance
Course Duration: 7 Weeks
Databricks Data Engineer
Module 1: MSSQL & TSQL Queries, Tuning
Ch 1: SQL Database Job Roles
- Database Intro
- OLTP, DWH, OLAP
- DBMS Basics
- Data Engineer Job Roles
Ch 2: Database Intro & Installations
- SQL Server Installations
- Instance & Collations
- SSMS Tool Installation
- Connections, Authentications
Ch 3: SQL Basics V1 (Commands)
- SQL Basics (DDL, DML, etc..)
- Creating Databases, Tables
- Data Inserts (GUI, SQL)
- Basic SELECT Queries
Ch 4: SQL Basics V2 (Commands, Operators)
- DDL: Create, Alter, Drop
- DML: Insert, Update, Delete
- DQL: Select, Fetch
- SQL Operators
Ch 5: Data Types & Variables
- Integer, Character Data Types
- Decimal & Boolean Data Types
- Date and Time Data Types
- SQL_Variant Type
Ch 6: Data Imports
- Data Imports with Excel
- Data Types Detection
- OLE-DB Connections
- ORDER BY, TOP, OFFSET
Ch 7: Schemas & Batches
- Schemas, Table Grouping
- Real-world Banking Database
- 2 Part, 3 Part, 4 Part Naming
- Batch & “Go” Command
Ch 8: Constraints, Keys & RDBMS
- Null, Not Null Constraints
- Unique Key & Check
- Primary Key & Default
- Foreign Keys, DB Diagrams
Ch 9: Normal Forms & RDBMS
- Normal Forms: 1 NF, 2 NF
- 3 NF, BCNF and 4 NF
- 1:1, 1:M, M:1 Cardinality
- Self Referencing Keys, ER Models
Ch 10: Joins & Queries
- Joins & TSQL Queries
- Inner Joins, Matching Data
- Outer Joins: Left, Right, Full
- Self Joins, Conditions
Ch 11: Sub Queries
- Sub Queries
- Nested Queries
- Correlated Sub Queries
- Union, Union All
Ch 12: Group By Queries
- Group By, Having
- Cube( ) & Rollup( )
- Grouping( )
- IsNull(), Coalesce()
Ch 13: Joins with Group By, Sub Queries
- Join, Group By, Sub Queries
- IIF(), CASE Statement
- EXISTS, NOT EXISTS
- Query Execution Order
Ch 14: Views & RLS
- Views: Realtime Usage
- DML, SELECT with Views
- WITH CHECK OPTION
- RLS, Important System Views
Ch 15: Functions & Queries
- Scalar, Table Value Functions
- Variables & Parameters
- Date Time, Conversion Functions
- String, Aggregated Functions
Ch 16: Advanced SQL, Window Functions
- Window Functions (Rank)
- Row_Number, DenseRank
- Partition By, Lead & Lag
- Pivot, UnPivot, Running Totals
Ch 17: Stored Procedures – 1
- Stored Procedures, Parameters
- SELECT & Conditional DML
- IF Statement, SP Recompilation
- System Stored Procedures
Ch 18: Stored Procedures – 2
- Merge Statement (Upsert)
- Merge with OLTP & DWH
- Matched and Not Matched
- Merge & SP Recompilations
Ch 19: Triggers & Automations
- DDL & DML Triggers
- For / After Triggers
- Instead Of Triggers
- Disabling DMLs Triggers
Ch 20: Transactions & ACID
- Auto Commit & Explicit
- Commit, Rollback, ReadPast
- Checkpoint, Query Blocking
- TRY…CATCH, Error Handling
Ch 21: SQL Query Performance & Indexing
- Clustered, NonClustered Indexes
- Execution Plans, Tuning Queries
- SARGable Queries
- Query Optimization Examples
Ch 22: CTEs & Tuning
- Common Table Expression
- CTEs for Retrieval, DML
- Data Cleansing Techniques
- Duplicate Detection/Removal
Ch 23: Temp Tables & Query Techniques
- Local & Global Temp Tables
- SELECT..INTO Statement
- Cursor Basics – When to Use & Avoid
- NULLIF, TSQL Queries
Ch 24: Bonus / Advanced Module: SQL Server Internals
- Database Engine Components
- Parser, Compiler & Optimizer
- Checkpoint, SQL OS
- Memory Manager & IO Managers
Module 2: Databricks, PySpark, Spark, Unity Catalog
Ch 1: Databricks Introduction
- Cloud ETL, DWH
- Databricks Concepts
- ETL, Lakehouse & Big Data
- Databricks Workspace UI
Ch 2: Databricks Architecture
- Two Plane Architecture
- Databricks Runtime (DBR)
- Spark Compute Concepts
- Databricks APIs
Ch 3: Unity Catalog
- Unity Catalog Concepts
- Managed & External
- Lineage, Data Governance
- Genie AI with Unity Catalog
Ch 4: Databricks Operations (GUI)
- Catalog & Schema Creations
- Volumes, Files & Tables
- Catalog Explorer
- Need for ETL
Ch 5: Spark SQL
- Spark SQL Notebooks
- Catalog, Schemas
- Tables, DDL Operations
- Spark Data Types & Clones
Ch 6: Spark Queries
- Data Inserts, Sequences
- Spark Joins
- Aggregations
- Data Analytics
Ch 7: Spark SQL: Functions
- Aggregate Functions
- Math, Sort Functions
- String, DateTime Functions
- Window & Null Functions
Ch 8: Spark SQL: Time Travel
- Time Travel Concepts
- HISTORY, EXTENDED
- Versions & Time Stamp
- Time Travel Settings
Ch 9: Python Introduction, Print
- Python Intro & Versions
- Python Implementations
- Python Print(), display()
- Single, Multiline Statements
Ch 10: Python Variables
- Variable Declarations
- Variable Values
- Multi Variable Values
- Type Casting, Collections
Ch 11: Python Operators
- Arithmetic, String Operators
- Logical, Assignment Operators
- Comparison, Format Operators
- Indexing, Bitwise Operators
Ch 12: Python Data Types
- Integer, Float Data Types
- String, List Data Types
- Dictionary Data Type
- Tuple Data Type
Ch 13: Python Control Statements
- If … Else Statement
- ELIF & ELSE IF Statements
- OR, AND Concepts
- FOR and WHILE Loops
Ch 14: Python Modules & DataFrames
- Pandas, NumPy
- DataFrame Concepts
- Handling Nulls
- Data Cleansing Concepts
Ch 15: Python DataFrames Transformations
- Concat(), Indexing
- Merge()
- Join KIND, ON Clauses
- Merging 3 Dataframes
Ch 16: PySpark Concepts
- Python Vs PySpark
- PySpark DataFrames
- select(), filter()
- withColumn()
Ch 17: Medallion Architecture – 1
- File Data Sources
- Bronze, Silver and Gold
- Temp Views, Aggregations
- Spark Tables (Parquet)
Ch 18: Medallion Architecture – 2
- Azure SQL DB Connections
- Joins & Aggregations
- Gold Data Consumption
- Bronze → Silver → Gold → BI/Analytics
Ch 19: Databricks Delta Lake
- Schema Evolution
- Delta Table API
- MERGE / Upsert Operations
- Delta Transaction Log
Ch 20: PySpark: Widgets
- Parameters, Text Widgets
- dbutils() & get() Functions
- Widget Prompts, Edits
- UI & JSON for Widgets
Ch 21: Lake Flow Jobs
- Workflows & CRON
- Job Compute, Running Tasks
- Python Script Tasks, Dependencies
- Concurrency, Branch Control
Ch 22: PySpark: Auto Loader
- Cloud Files & Checkpoints
- Data Stream, Schemas
- Schema Evaluation Modes
- File Ingestions, Rescued Column
Ch 23: LakeFlow Declarative Pipelines
- SDP: Spark Declarative Pipelines
- Delta LIVE Tables, Data Streams
- Bronze, Silver, Gold Data
- Data Quality, Materialized Views
Ch 24: Databricks Optimizations
- Lazy Evaluation, Data Skew
- Data Shuffling, Partitions
- Broadcast Joins, Vacuum
- Liquid Clusters, Optimize, Z-Order
Ch 25: Databricks Security, AI
- ACL: Access Control List
- Workspace & Catalog Security
- Schema, Volume Security
- Table & Column Security
Ch 26: Databricks with Power BI
- Access Keys (Tokens)
- Server Host, HTTP Path
- Spark Connectors
- Databricks Connectors
Ch 27: Genie AI
- Unity Catalog & Genie AI
- AI Components in Databricks
- Debugging Controls
- Using AI for Notebook Design
Ch 28: GitHub & Asset Bundle
- GitHub & GIT
- Branches, Asset Bundle
- Integrating GIT
- Process Integration
Ch 29: Apache Airflow
- Apache Airflow Concepts
- Python Scripts, Airflow Jobs
- Databricks Run Now Operator
- Databricks Submit Run Operator
Module 3: Realtime Projects
Real-Time Project
Project 1: HealthCare Domain
Project Requirement:
Solve 20+ Real-World Healthcare Business Requirements.
Project Workflow:
Database Design → SQL → Data Analysis → Performance Optimization
Project Operational Flow:
Healthcare DB → Patients → Doctors → Appointments → Treatments → Billing → Insurance → SQL
Analysis → Stored Procedures → Performance Tuning → Business Reports
Business Requirements:
Monthly Hospital Revenue, Top Doctors By Patients Treated, Repeat Patients, Department Performance,
Average Treatment Cost, Unpaid Bills, Insurance Claim Analysis, Patient Trends, Month-Over-Month
Revenue And Top Procedures…
Project 2: E-Commerce Domain
Project Title:
Retail Sales Analytics Platform using Databricks (Medallion Architecture)
Project Overview
Students will build a production-style data platform using Lakehouse Architecture (Bronze, Silver,
and Gold), implementing modern ETL practices, data quality validation, incremental processing,
orchestration, optimization, and reporting.
Business Scenario
A multinational retail company receives daily data from multiple operational systems. The
company wants to build a centralized analytics platform to:
- Consolidate data from different business domains
- Improve data quality and consistency
- Track sales performance across regions
- Analyse customer purchasing behaviour
- Monitor inventory levels
- Generate business KPIs for decision-makers
- Deliver Power BI dashboards with near real-time insights
Source Systems
Students will work with multiple datasets including:
- Customer Master
- Product Master
- Orders
- Inventory
- Region Master
Technologies Covered
- Apache Spark
- PySpark
- Spark SQL
- Delta Lake
- Unity Catalog
- Databricks Workflows
- Git Integration
Resume Highlights
After completing this project, you can confidently showcase experience in:
- PySpark & Spark SQL
- Delta Lake
- Medallion Architecture
- ETL Pipeline Development
- Incremental Data Processing
- Data Quality & Validation
- Unity Catalog
- Workflow Automation
- Performance Optimization
Module 4: Databricks Data Engineer Certification Guidance
👉 Exam Q & A, Scenarios
👉 Certification Exam Objectives
👉 Topic-Wise Revision
👉 Scenario-Based Questions
👉 Practice Assessments
👉 Mock Exams
👉 Databricks Interview Questions
👉 Real-Time Scenario Discussions
👉 Resume Project Explanation
👉 Technical Mock Interview
What is the Databricks Data Engineer Associate Training?
This training covers Databricks concepts end-to-end including Spark SQL, PySpark, Delta Lake, Lakehouse, Auto Loader, DLT, Unity Catalog, Workflows, Streaming, Medallion Architecture, and Real-Time Projects.
Who should join this course?
Aspiring Data Engineers, Cloud Engineers, BI Developers, Data Science Engineers, and freshers who want to build a strong career in Databricks and modern Data Engineering.
What modules are included in this training?
Module 1: MSSQL
Module 2: Python
Module 3: Databricks (Complete)
Module 4: Databricks Data Engineer Associate Exam Guidance
Is SQL included as part of the training?
Yes. SQL Server basics to advanced topics including DDL, DML, Joins, Constraints, Keys, Views, Procedures, Functions, CTEs, Tuning, Indexes, Group By, Subqueries, Transactions, and Window Functions.
Do I need Python knowledge to learn Databricks?
Yes, and this course teaches Python from scratch including data types, loops, functions, modules, file handling, exception handling, and full pandas for ETL.
What Databricks basics will I learn?
You will learn Workspace, Notebooks, Clusters, Filesystems, Catalogs, Schemas, and Databricks Architecture including Spark and Lakehouse fundamentals.
Does the course include Spark SQL?
Yes. Spark SQL API, creating schemas, altering columns, unions, math functions, sort functions, string functions, date/time functions, conditional logic, expr() and complex SQL expressions.
Will I learn PySpark in detail?
Yes. Creating DataFrames, reading/writing CSV/JSON/ORC/Parquet, schema inference, grouping, filtering, joins, union, pivot/unpivot, transformations, and rendering outputs.
Is Unity Catalog included in the curriculum?
Yes. Managed tables, external tables, volumes, catalogs, schemas, views, access control, workspace binding, lineage, metastore, system tables, and securable objects.
Will I learn Data Ingestion & Auto Loader?
Yes. Auto Loader streaming ingestion, schema inference, evolution, streaming reads/writes, cancellations, and workspace modules.
Is Medallion Architecture taught?
Yes. Bronze, Silver, Gold layers, aggregated loads, temp views, parquet tables, file/table sources, and building reliable pipelines using Medallion principles.
What Delta Lake concepts does this course cover?
Delta Table API, delete/update/merge, time travel, history, schema evolution, DML operations, retention, transaction logs, and Delta Lake SCD Type 2 implementation.
Will I learn SCD Type 2 in real-time?
Yes. Incremental loads, new/existing record handling, history retention, upserts, and automation using Delta Lake and notebooks.
Does the course include Streaming & Structured Streaming?
Yes. Streaming simulations, micro-batches, schema evolution, watermarking, time-based aggregations, triggers, and Delta streaming pipelines.
Do you cover Databricks Workflows (Jobs)?
Yes. Jobs scheduling, CRON, task dependencies, branching logic, passing parameters into notebooks/py scripts, concurrent executions, and job clusters.
Is Databricks Tuning part of the training?
Yes. Explain plans, lazy evaluation, caching, data shuffling, broadcast joins, partitioning, data skipping, Z-ordering, Liquid Clustering, and Spark configs.
Will I learn GitHub Integration?
Yes. Git prerequisites, linking GitHub with Databricks, Git folders, adding modules, version control, code sync, and pipeline updates.
Does the course include Delta Live Tables (DLT)?
Yes. Pipeline clusters, Data Quality checks, declarative pipelines, streaming datasets, parameterization, and DLT streaming live tables.
Is a real-time project included?
Yes. E-Commerce/Banking/Sales projects with requirements, solutions, FAQs, architecture flow, interview questions, and resume guidance.
Is exam preparation for Databricks Data Engineer Associate included?
Yes. Exam guidance, sample questions, mock exams, and hands-on practice for the certification.
Training Modes
Why Choose SQL School
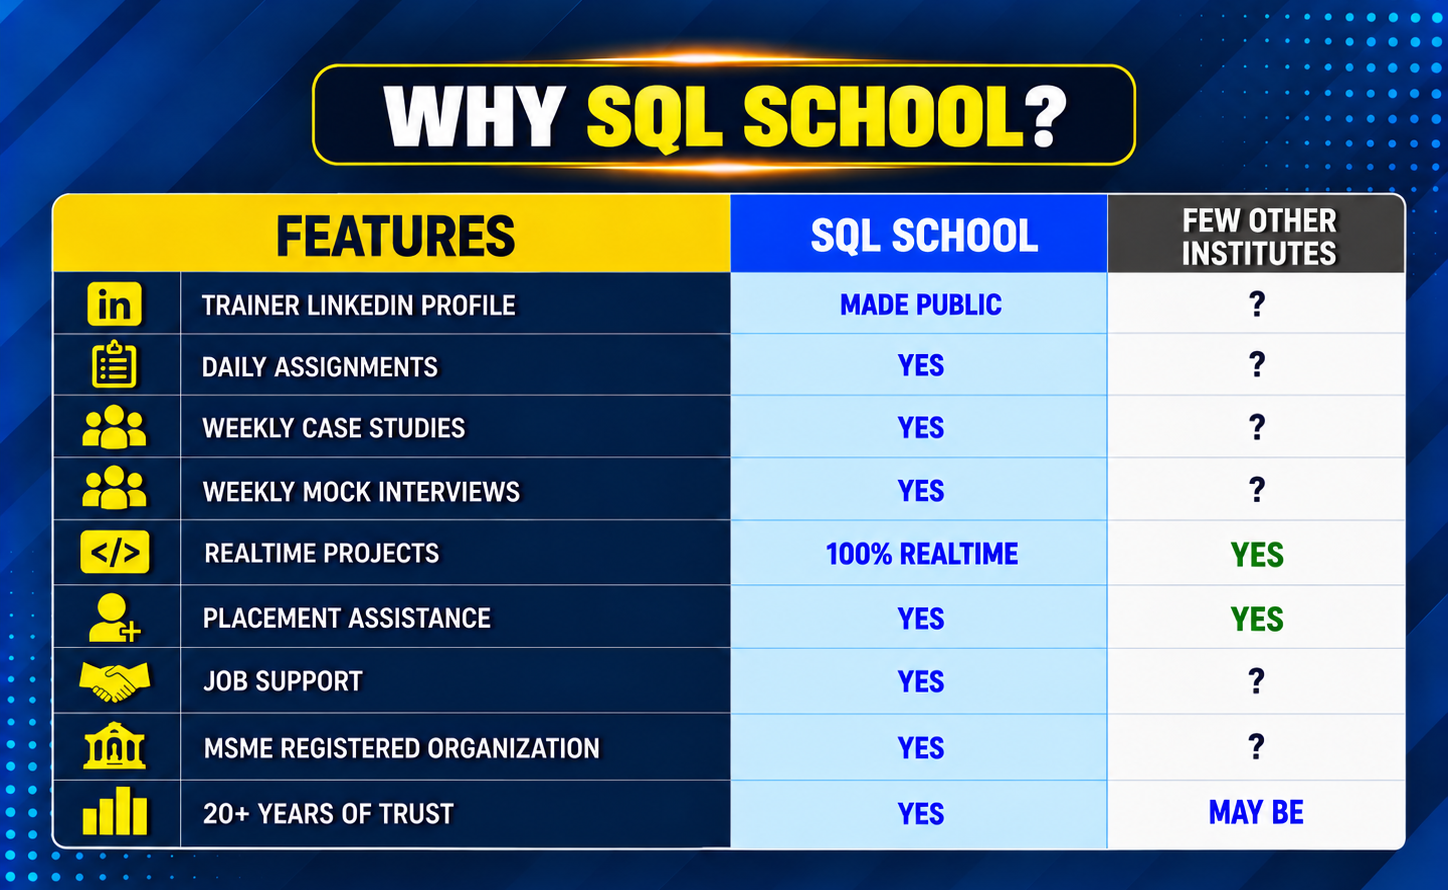
- 100% Real-Time and Practical
- ISO 9001:2008 Certified
- Concept wise FAQs
- TWO Real-time Case Studies, One Project
- Weekly Mock Interviews
- 24/7 LIVE Server Access

- Realtime Project FAQs
- Course Completion Certificate
- Placement Assistance
- Job Support
- Realtime Project Solution
- MS Certification Guidance