#Azure Data Engineer With AI

Azure Data Engineer is a prominent job role responsible for design of Data Warehouses (DWH). This trending job stream involves Extraction (E) of data from various sources, perform data mashup and Transformations (T) and Loading the data (L) into Warehouse and Lakehouse platforms. With AI & CoPilot we can implement this ETL & DWH with ease !

Training Highlights

✅ ADF, Synapse with Big Data
✅ Lakehouse & Medallion Architecture
✅ Python, PySpark for AI Pipelines
✅ Eventstream & Real-Time Analytics
✅ ML Integration with Azure ML
✅ Delta Lake & Serverless Pools
✅ Security with RBAC & Key Vault
✅ Databricks in AI Workflows
✅ Real Time Project
✅ 1:1 Mentorship, Resume

Modules We Learn

✅ Module 1: MSSQL & TSQL, Tuning
✅ Module 2: Azure Data Engineer
✅ Module 3: Databricks AI (GenAI, LLM, Agents, RAG)
✅ Module 4: Real-Time Projects for Data Engineering

Course Duration: 14 Weeks
Azure Data Engineer
With Gen AI Contents:

Module 1: MSSQL & TSQL, Tuning

Ch 1: SQL Database Job Roles

  • Database Intro
  • OLTP, DWH, OLAP
  • DBMS Basics
  • Data Engineer Job Roles

Ch 2: Database Intro & Installations

  • SQL Server Installations
  • Instance & Collations
  • SSMS Tool Installation
  • Connections, Authentications

Ch 3: SQL Basics V1 (Commands)

  • SQL Basics (DDL, DML, etc..)
  • Creating Databases, Tables
  • Data Inserts (GUI, SQL)
  • Basic SELECT Queries

Ch 4: SQL Basics V2 (Commands, Operators)

  • DDL: Create, Alter, Drop
  • DML: Insert, Update, Delete
  • DQL: Select, Fetch
  • Add, Truncate Statements
  • SQL Operators

Ch 5: Data Types & Variables

  • Integer Data Types
  • Character, MAX Data Types
  • Decimal & Boolean Data Types
  • Date and Time Data Types
  • SQL_Variant Type

Ch 6: Data Imports

  • Data Imports with Excel
  • Data Imports with CSV
  • Data Types Detection
  • OLE-DB Connections
  • ORDER BY, TOP, OFFSET

Ch 7: Schemas & Batches

  • Schemas & Table Grouping
  • Real-world Banking Database
  • 2 Part, 3 Part & 4 Part Naming
  • Batch Concept & “Go” Command

Ch 8: Constraints, Keys & RDBMS

  • Null, Not Null Constraints
  • Unique Key & Check
  • Primary Key Constraint
  • Foreign Keys, Default
  • DB Diagrams & ER Models

Ch 9: Normal Forms & RDBMS

  • Normal Forms: 1 NF, 2 NF
  • 3 NF, BCNF and 4 NF
  • 1:1, 1:M, M:1 Cardinality
  • Cascading Keys, Self Referencing Keys

Ch 10: Joins & Queries

  • Joins: Table Comparisons
  • Inner Joins & Matching Data
  • Outer Joins: LEFT, RIGHT
  • Full Outer Joins & Aliases
  • Self Joins & Aliases

Ch 11: Sub Queries

  • Basic Sub Queries
  • Aggregations
  • Combining Queries
  • Correlated Sub Queries
  • UNION, UNION ALL

Ch 12: Group By Queries

  • Group By, Distinct
  • GROUP BY, HAVING
  • Cube( ) and Rollup( )
  • Sub Totals & Grand Totals
  • Grouping( ) & Usage
  • ISNULL, COALESCE

Ch 13: Joins with Group By, Sub Queries

  • 3 Table, 4 Table Joins
  • Join Queries & WHERE
  • Join & Group By, Sub Queries
  • IIF(), CASE Statement
  • EXISTS, NOT EXISTS
  • Query Execution Order

Ch 14: Views & RLS

  • Views: Realtime Usage
  • DML, SELECT with Views
  • WITH CHECK OPTION
  • Row Level Security (RLS)
  • Important System Views

Ch 15: Functions & Queries

  • User Defined Functions
  • Scalar, Table Value Functions
  • Variables & Parameters
  • Date & Time Functions
  • String Functions
  • Aggregated Functions
  • Data Conversion Functions

Ch 16: Advanced SQL & Window Functions

  • Window Functions (Rank)
  • Row_Number, DenseRank
  • Partition By & Order By
  • Lag & Lead Functions
  • Pivot, UnPivot
  • Running Totals
  • Moving Average

Ch 17: Stored Procedures – 1

  • Stored Procedures: Realtime Use
  • Parameters Concept with SPs
  • Procedures with SELECT
  • System Stored Procedures
  • Stored Procedures, Tuning

Ch 18: Stored Procedures – 2

  • Merge Statement (Upsert)
  • Merge with OLTP & DWH
  • Matched and Not Matched
  • Merge & SP Recompilations

Ch 19: Triggers & Automations

  • Need for Triggers in Real-world
  • DDL & DML Triggers
  • For / After Triggers
  • Instead Of Triggers
  • Disabling DMLs Triggers

Ch 20: Transactions & ACID

  • Auto Commit Transaction
  • Explicit Transactions
  • COMMIT, ROLLBACK
  • Checkpoint & Query Blocking
  • READPAST, LOCKHINT
  • TRY…CATCH & Error Handling

Ch 21: SQL Query Performance & Indexing

  • Clustered vs Nonclustered Indexes
  • Index Seek vs Scan
  • Execution Plans
  • Tuning Queries
  • Indexing JOIN/WHERE columns
  • Query Optimization Examples

Ch 22: CTEs & Tuning

  • Common Table Expression
  • CTEs for Data Retrieval
  • CTEs for DML Operations
  • Data Cleansing Techniques
  • Duplicate Detection/Removal

Ch 23: Temp Tables & Query Techniques

  • Local & Global Temp Tables
  • SELECT..INTO Statement
  • Cursor Basics – When to Use & Avoid

Ch 24: Bonus / Advanced Module: SQL Server Internals

  • Database Engine Components
  • Parser, Compiler & Optimizer
  • Parsing and Compilation
  • Memory Manager & IO Managers

Real-Time Project on HealthCare Domain
Project Requirement:
Solve 20+ Real-World Healthcare Business Requirements.

Project Workflow:
Database Design → SQL Development → Data Analysis → Performance Optimization

Project Operational Flow:
Healthcare DB → Patients → Doctors → Appointments → Treatments → Billing → Insurance → SQL
Analysis → Stored Procedures → Performance Tuning → Business Reports

Business Requirements:
Monthly Hospital Revenue, Top Doctors By Patients Treated, Repeat Patients, Department
Performance, Average Treatment Cost, Unpaid Bills, Insurance Claim Analysis, Patient Trends,
Month-Over-Month Revenue And Top Procedures…

Module 2: Azure Data Engineer

Section 1: Databricks (Spark, PySpark, Big Data, Genie AI)
Ch 1: Databricks Introduction

  • Cloud ETL, DWH
  • Cloud Computing
  • Databricks Concepts
  • ETL Components
  • Lakehouse & Big Data Concepts
  • Databricks Workspace UI
  • Databricks Account

Ch 2: Databricks Basic Operations

  • Catalog
  • Schema
  • Volumes, Files
  • Tables
  • Need for ETL
  • Need for PySpark
  • Catalog Explorer

Ch 3: Databricks Architecture

  • Databricks Architecture
  • Databricks Lakehouse Architecture
  • Databricks Runtime (DBR)
  • RDD & DAG
  • Spark Compute Concepts
  • Workers & Drivers
  • Databricks Framework
  • Databricks APIs

Ch 4: Unity Catalog

  • Unity Catalog Concepts
  • Catalogs & Volumes
  • Parquet & Delta Tables
  • Managed & External Tables
  • Lineage, Data Governance
  • Spark Table Creations

Ch 5: Spark SQL: Basics

  • Spark SQL Notebooks
  • Creating Catalog
  • Creating Schemas
  • Creating Tables
  • DDL Operations
  • Spark Data Types
  • Notebooks: Exports, Clone

Ch 6: Spark SQL: Functions

  • Math, Sort Functions
  • String, DateTime Functions
  • Conditional Statements
  • SQL Expressions with expr()
  • Volume for our Data Assets
  • File Formats, Schema Inference
  • Spark SQL Aggregations

Ch 7: Spark SQL: Time Travel

  • Time Travel Concepts
  • Spark DB: Logical Architecture
  • Spark DB: Physical Store
  • Data File & Log File Store
  • Time Travel
  • DESCRIBE, EXTENDED
  • HISTORY
  • Version Numbers

Ch 8: Python: Introduction, Print

  • Python Introduction
  • Python Versions
  • Python Implementations
  • Python in Spark (PySpark)
  • Python Print()
  • Single, Multiline Statements

Ch 9: Python: Variables

  • Python Variables
  • Variable Declarations
  • Variable Values
  • Multi Variable Values
  • Common Variable Values
  • Realtime use of Variables

Ch 10: Python: Operators

  • Need for Operators
  • Arithmetic Operators
  • Assignment Operators
  • Comparison Operators
  • Operator Precedence
  • Operands in Python

Ch 11: Python: Control Statements

  • Python Control Structures
  • If … Else Statement
  • Short Hand If
  • ELIF & ELSE IF Statements
  • OR, AND Concepts
  • Python Loops

Ch 12: Python: Data Types

  • Python Data Types
  • Integer / Int Data Types
  • Float, String Data Types
  • List Data Type
  • Dictionary Data Type
  • Tuple Data Type

Ch 13: Python: Modules & DataFrames

  • Python Modules
  • Pandas, NumPy
  • DataFrame Concepts
  • Handling Nulls
  • Data Cleansing Concepts
  • Python Functions

Ch 14: PySpark DataFrames & Transformations

  • Creating PySpark DataFrames
  • Reading Data Sources
  • select(), filter(), withColumn()
  • Handling NULL Values
  • Data Type Casting
  • Joins, Aggregations
  • Window Functions
  • Writing DataFrames

Ch 15: Medallion Architecture – 1

  • Medallion Architecture
  • Aggregated Data Loads
  • Bronze, Silver and Gold
  • Temp Views
  • Spark Tables (Parquet)
  • Work with File Sources

Ch 16: Medallion Architecture – 2

  • Medallion Architecture
  • Azure SQL DB Connections
  • Joining Source Tables
  • Data Frames, Temp Views
  • Aggregated Data Loads
  • Gold Data Consumption
  • Raw Sources → Bronze → Silver → Gold → BI/Analytics

Ch 17: Delta Lake

  • Databricks Delta Lake
  • Schema Evolution
  • Azure SQL DB Connections
  • DataFrames, Temp Views
  • Delta Table API
  • MERGE / Upsert Operations
  • Version History & Data Retention
  • Delta Transaction Log

Ch 18: PySpark: Widgets

  • PySpark Parameters
  • Text Widgets
  • User Parameters
  • Manual Executions
  • Automations
  • UI & JSON For Widgets

Ch 19: Lake Flow Jobs

  • Workflows & CRON
  • Job Compute, Running Tasks
  • Python Script Tasks
  • Parameters into Notebook Tasks
  • Parameters into Python Script Tasks
  • Concurrent Executions, Dependencies
  • Branching Control

Ch 20: PySpark: Auto Loader

  • Cloud Files Architecture
  • Checkpoint Configurations
  • Schema Location
  • Checkpoint Location
  • Data Stream
  • Schema Evaluation Modes
  • Incremental File Ingestion
  • Rescued Data Column

Ch 21: LakeFlow Declarative Pipelines

  • SDP: Spark Declarative Pipelines
  • Delta LIVE Tables
  • Streaming Data Loads
  • Bronze, Silver, Gold Data
  • Materialized Views
  • Pipeline Clusters
  • Data Quality Checks

Ch 22: Databricks Optimizations

  • Lazy Evaluation
  • Explain Plan
  • Caching, Data Shuffling
  • Broadcast Joins
  • Partitions, Data Skew
  • Liquid Clustering
  • VACUUM
  • OPTIMIZE, Z Ordering

Ch 23: Databricks Security, AI

  • ACL: Access Control List
  • Workspace Access Control
  • Catalog Security
  • Schema, Volume Security
  • Table Security
  • Column Security

Ch 24: Databricks with Power BI

  • Workspace Settings
  • Access Keys (Tokens)
  • Server Host
  • HTTP Path
  • Spark Connectors
  • Databricks Connectors

Ch 25: Genie AI

  • Genie AI Concepts
  • Unity Catalog
  • AI Components in Databricks
  • Debugging Controls
  • Using AI for Notebook Design

Ch 26: GitHub & Asset Bundle

  • GitHub Concepts
  • GIT: Main, Branches
  • Asset Bundle
  • Integrating GIT with Asset Bundle
  • Process Integration

Ch 27: Apache Airflow

  • Apache Airflow Concepts
  • Airflow Operators & DAG
  • Python Scripts for Airflow
  • DatabricksRunNowOperator
  • DatabricksSubmitRunOperator
  • Airflow Jobs

Section 2: Azure Data Factory & Synapse, ADLS
Ch 1: Azure Fundamentals

  • Cloud Introduction, Azure
  • Cloud Implementations
  • Azure Account, Subscription
  • Azure ETL & DWH Resources
  • Azure Storage, IoT Resources

Ch 2: Azure Storage & ADLS

  • Azure Data Lake Storage
  • Azure BLOB Containers
  • Access Keys
  • SAS Keys
  • IAM & ACLs

Ch 3: Azure Deployments, Azure SQL

  • Azure SQL Server Deployment
  • Azure SQL DB Deployment
  • Azure SQL Database (OLTP)
  • Azure Firewall Rules
  • Connections from SSMS Tool

Ch 4: Azure SQL DB Migrations

  • Azure Storage Account
  • On-Premise SQL DB, bacpac
  • Azure SQL DB Migration
  • SQL Server Imports from BLOB
  • Migration Verifications

Ch 5: Azure Synapse Analytics (DWH)

  • Synapse Pool Architecture
  • Control Node, Compute Node
  • DMS (Data Movement Service)
  • Azure DWH Tables: Partitions
  • Distributions & MAXDOP

Ch 6: Azure Data Factory – Pipelines

  • ADF Intro & Pipeline Artifacts
  • Integration Runtime (IR)
  • Linked Services, Datasets
  • Copy Data Activity
  • Azure SQL DB Loads
  • Azure Synapse Analytics Writes
  • Pipeline Validation, Runs

Ch 7: ADF: Azure Blob Data Loads

  • ADF Author & Pipeline Runs
  • Azure BLOB Storage Access
  • Storage Containers in ADF
  • Pipeline Staging
  • Pipeline Logging
  • Validations & Schedules

Ch 8: Table Incremental Loads

  • Implement SCD with ADF
  • Self Hosted IR: Realtime Use
  • On-premise Data: Incr Loads
  • Copy Method: Upsert, Keys
  • Staging & ADF Optimizations
  • Pipeline Logging

Ch 9: ADF Data Flow – 1

  • Creating Data Flow Items
  • Using Multiple Sinks
  • Conditional Split Transformation
  • Select, Sort, Union, Loops
  • ADF Debug Options

Ch 10: ADF Data Flow – 2

  • Working with Multiple Tables
  • Join Transform, Broadcast
  • Surrogate Keys, Derived Cols
  • ETL Loads Dates, Sink Options
  • Aggregated Data Loads

Ch 11: ADF Data Flow – 3

  • Pivot Transformation
  • Group By & Pivot Keys
  • Column Pattern, Deduplicate
  • Lookup, Cached Lookup
  • Tuing Transformations
  • Tuning Data Flow, Spark

Ch 12: ADF Data Flow – 4

  • Get Metadata
  • IF & Lookup Transformation
  • Cache Lookup
  • Broadcast Options
  • DIU, DOCP

Ch 13: ADF Parameters, Security

  • Linked Service Parameters
  • Creating Logins & Users
  • Schemas, ETL Permissions
  • Logins Parameters in ADF
  • Dynamic Linked Services

Ch 14: SCD & ETL with Control Tables

  • ADF Templates in Realtime
  • Incremental Loads (SCD)
  • Control Tables, Watermarks
  • Lookup Activity, Delta Queries
  • SP Activity & Parameters
  • Pipeline Parameters, SPs

Ch 15: ADF Metrics, Alerts

  • Azure Insights
  • Azure Metrics for ADF
  • Azure Metrics for Synapse
  • Alerts and Notifications
  • Action Groups, Tuning Options

Ch 16: ADF with DevOps & CI/CD

  • Git repositories and branching
  • ADF Git integration
  • Development / Test / Production environments
  • Parameterized deployments
  • Production release workflow

Ch 17: Azure Databricks

  • Azure Databricks Deployments
  • Azure Databricks Regions
  • Classic Deployments
  • Access connector for Databricks

Ch 18: Azure Databricks with ADLS

  • Creating IAM Users
  • ADLS Security for Databricks
  • Creating Service Principals
  • Enterprise Applications
  • Client ID, Secret ID
  • External Tables (Delta)

Ch 19: Azure Stream Analytics

  • Azure IoT Hubs
  • Azure Stream Analytics
  • LIVE Data Ingestions
  • SAQL Queries
  • Stream Analytics Jobs
  • Handling JSON Data

Ch 20: Azure Key Vaults

  • Azure Key Vaults
  • Azure Keys & Secrets
  • Access Policies
  • Secret Management
  • Managed Identity

Ch 21: Azure Logic Apps

  • Azure Logic Apps
  • Logic Apps & Automations
  • Azure Events
  • Azure Triggers & Signals
  • ADLS with Logic Apps

Module 3: Databricks AI (GenAI, LLM, Agents, RAG)

Ch 1: AI Concepts

  • Artificial Intelligence, Machine Learning and Deep Learning
  • Generative AI concepts and applications
  • Traditional AI vs Generative AI
  • Generative AI use cases in Data Engineering

Ch 2: Large Language Models & Prompt Engineering

  • Introduction to LLMs and foundation models
  • Tokens, context windows and inference
  • Prompt engineering techniques
  • Structured outputs and JSON responses
  • Introduction to embeddings and similarity search

Ch 3: Generative AI with Databricks

  • Databricks AI ecosystem overview
  • Databricks AI Playground
  • Foundation Model APIs
  • Model serving endpoints
  • Accessing LLMs using Python

Ch 4: Databricks AI Functions

  • Introduction to Databricks AI functions
  • Using ai_query() in SQL
  • Calling foundation models from SQL
  • AI-powered text processing
  • Structured response generation

Ch 5: Intelligent Data Processing

  • Text classification using AI
  • Sentiment analysis
  • AI-based information extraction
  • Data enrichment using LLMs
  • Working with customer reviews and feedback

Ch 6: Unstructured Data Engineering

  • Working with PDF, JSON and text files
  • Ingesting unstructured data
  • Document parsing and preprocessing
  • PySpark pipelines for AI-ready datasets
  • Storing processed data in Delta Lake

Ch 7: AI Data Pipelines & Governance

  • Delta Lake for AI datasets
  • Unity Catalog for data governance
  • Incremental data processing
  • Embedding generation and refresh pipelines
  • Automating AI-based ETL workflows

Ch 8: Introduction to RAG

  • What is Retrieval-Augmented Generation?
  • Limitations of traditional LLM applications
  • RAG vs fine-tuning
  • RAG architecture and components
  • Enterprise RAG use cases

Ch 9: Document Processing for RAG

  • PDF and document ingestion
  • Extracting text from documents
  • Document parsing and cleaning
  • Text chunking strategies
  • Preparing documents for vector search

Ch 10: Vector Embeddings

  • Understanding text embeddings
  • Embedding models
  • Generating vector embeddings
  • Vector similarity concepts
  • Storing document embeddings

Ch 11: Databricks AI Search

  • Introduction to Databricks AI Search (Vector Search)
  • Vector indexes and index creation
  • Delta Sync indexes
  • Similarity search queries
  • Retrieving relevant document chunks

Ch 12: Building RAG Applications

  • Integrating vector retrieval with LLMs
  • Context retrieval and prompt augmentation
  • Generating context-aware responses
  • Building a PDF-based AI chatbot
  • Source citations and hallucination reduction

Ch 13: Advanced Retrieval Techniques

  • Semantic search vs keyword search
  • Hybrid search techniques
  • Reranking retrieved documents
  • Metadata-based filtering
  • Chunk-size optimization

Ch 14: Intelligent RAG Pipelines

  • Query rewriting
  • Multi-query retrieval
  • Structured RAG with SQL data
  • Combining Delta tables and document retrieval
  • Building hybrid structured/unstructured RAG applications

Ch 15: RAG Performance Optimization

  • Evaluating retrieval relevance
  • Answer groundedness
  • Improving retrieval accuracy
  • Reducing hallucinations
  • Latency and token

Module 4: Real-Time Projects for Data Engineering

Real-Time Project 1: Online Travel Data Engineering Platform
Project Objective:

Build an end-to-end Azure Data Engineering solution to process, transform, and analyze Online Travel
business data from multiple sources.

Skills Gained:

  • Data Ingestion & ETL Development
  • Azure Data Factory Pipelines
  • Data Orchestration (End to End)
  • Data Lake Architecture, RBAC
  • Real-Time Industry Experience
  • Azure IoT, Stream Analytics
  • Azure Databricks with Data Factory

Components For Project

  • ADF Pipelines
  • Databricks Notebooks
  • Synapse Analytics
  • Apache Spark Schemas
  • Monitoring & Alerts
  • CI/CD Deployment
  • End to End Integrations
  • IAM & Managed Identity

Real-Time Project 2: Retail Sales Analytics Platform using Databricks (Medallion, AI, Gen AI)
Project Overview
Students will build a production-style data platform using Lakehouse Architecture (Bronze, Silver, and
Gold), implementing modern ETL practices, data quality validation, incremental processing, orchestration,
optimization, and reporting.

Business Scenario
A multinational retail company receives daily data from multiple operational systems. The company wants
to build a centralized analytics platform to:

  • Consolidate data from different business domains
  • Improve data quality and consistency
  • Track sales performance across regions
  • Analyse customer purchasing behaviour
  • Monitor inventory levels with RAG, Agentic AI
  • Generate business KPIs, LLMs
  • Deliver Power BI dashboards with near real-time insights

Technologies Covered

  • PySpark
  • Spark SQL
  • Delta Lake
  • Unity Catalog
  • AI, Gen AI
  • Git, AirFlow

Project Workflow
Sources → ADLS → Bronze → Silver → Gold → Databricks Workflows → Power BI

Data Engineering Certifications
Exam 1: Databricks Data Engineer Associate

  • Exam Details
  • Exam Dumps
  • Scenario-Based Questions
  • Practice Assessments

Exam 2: Microsoft Databricks (DP-750)

  • Exam Details
  • Exam Dumps
  • Scenario-Based Questions
  • Practice Assessments

Resume Highlights
After completing this module, you can confidently showcase experience in:

  • PySpark & Spark SQL
  • Medallion Architecture
  • ETL Pipeline Development
  • Data Quality & Validation
  • Unity Catalog, AI, Gen AI, Agentic AI, LLMs
  • Automations, Optimizations

What is Azure Data Engineer with AI Job Role?

An Azure Data Engineer with AI specialization is a modern data professional responsible for designing, building, and maintaining end-to-end data solutions in Azure that integrate AI and machine learning capabilities. This role combines traditional data engineering tasks like data ingestion, transformation, storage, and performance tuning with advanced AI integrations such as Azure Cognitive Services, OpenAI APIs, Azure ML, and SynapseML to support intelligent analytics and predictive applications.

What are the Job Roles of an Azure Data Engineer with AI?

💼 Top Job Roles:

1️⃣ Build and manage scalable data pipelines using Azure Data Factory, Synapse & Data Lake
2️⃣ Integrate AI APIs (OpenAI, Azure Cognitive Services, Azure ML) into data workflows
3️⃣ Implement data models, warehouses, and real-time data solutions
4️⃣ Develop intelligent dashboards, semantic layers, and custom ML integrations
5️⃣ Ensure security, governance, and compliance of AI-powered data systems
6️⃣ Collaborate with data scientists, BI developers, and business stakeholders and more..!

What does our Azure Data Engineer with AI Training course contain?

The course is carefully curated with below module:
👉🏻Module 1: Microsoft SQL (TSQL)
👉🏻Module 2: Azure Data Engineer with AI
👉🏻Module 3: Azure AI, Co-Pilot

Who can join this course?

  •  Freshers interested in cloud BI and analytics
  • SQL/BI professionals expanding to AWS BI tools
  • ETL developers moving to AWS cloud solutions
  • Data analysts aiming for AWS BI certifications
  • Anyone looking to build enterprise BI solutions on AWS

No prior coding experience is required. All concepts are taught from scratch

What training modes are available?

Option 1:        LIVE Online Training  (100% Interactive, step by step, assignments)

Option 2:        Self Paced Videos (100% practical, step by step with concept wise assignments)

You may choose any one of these options, same curriculum!

I (Trainer) shall be available for doubts and clarifications, assignment check and review.

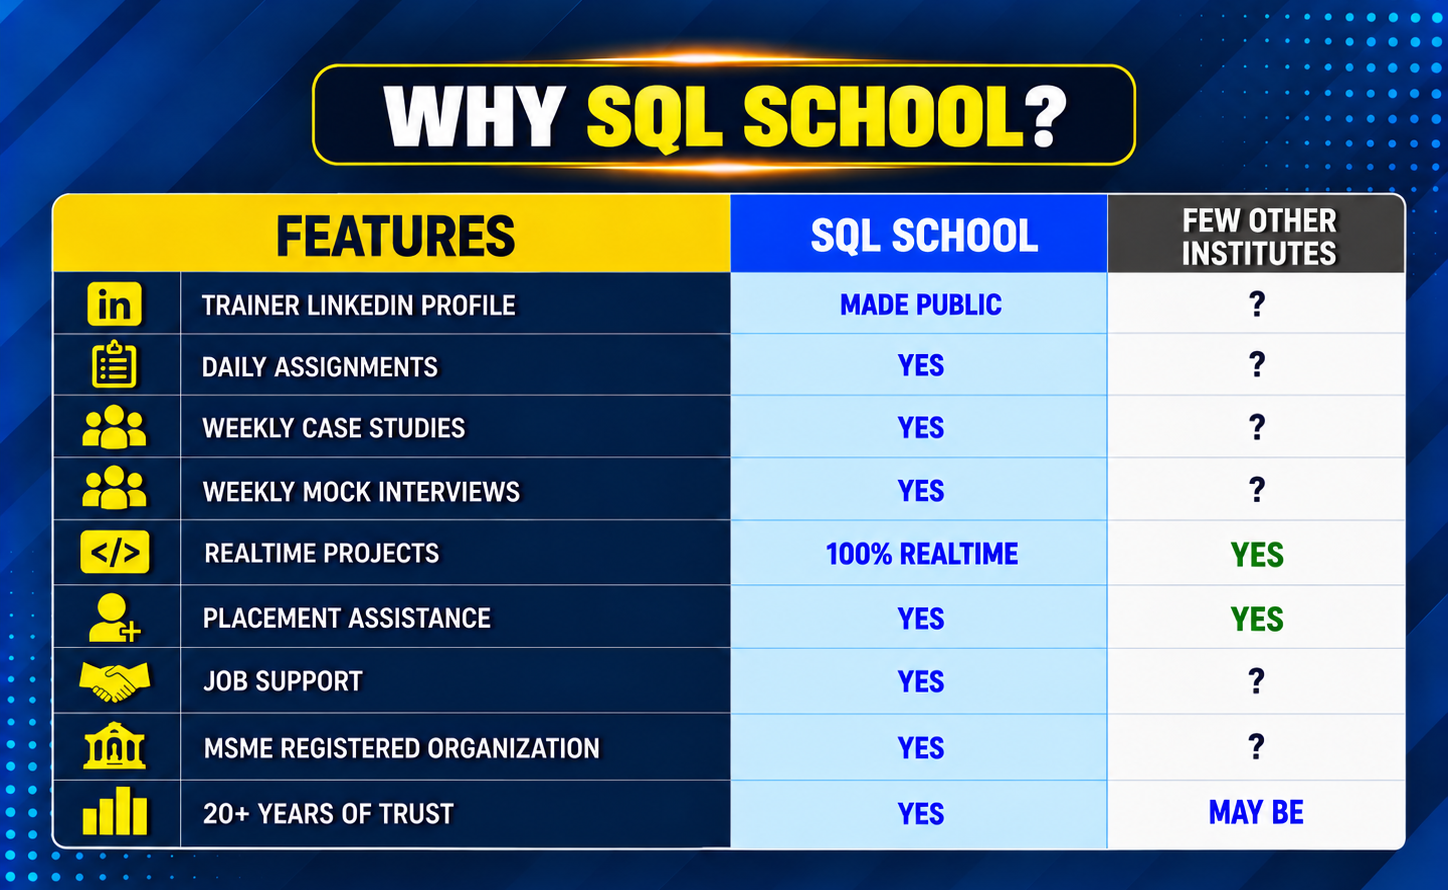
Why should I choose SQL School for Azure Data Engineer With AI training?

👉🏻 Every session is Practical, Step by Step with Concept wise FAQs !!

👉🏻 100% results with on-time practice.  Daily Tasks for every session.

👉🏻 Concept wise tasks be submitted before next class for Job Waiters / Starters.

👉🏻 Concept wise tasks due for submission by Weekends for Working Professionals.

Demo Videos

Why SQL SCHOOL?

Training Modes

Verified by MonsterInsights